简体中文 · Quick start · Agent setup · Benchmarks · Documentation · Releases


A semantic filter and hosted executor between your tools and your AI agent. Capture command output, search results, browser controls or logs inside the CLI. Let Jev judge them using the agent's task and context. Return relevant evidence and unresolved IDs instead of an entire raw dump. New in 0.3: let the CLI act on a web page or a desktop app, or survey thousands of records, with the same typed and inspectable decisions. Hosted execution →
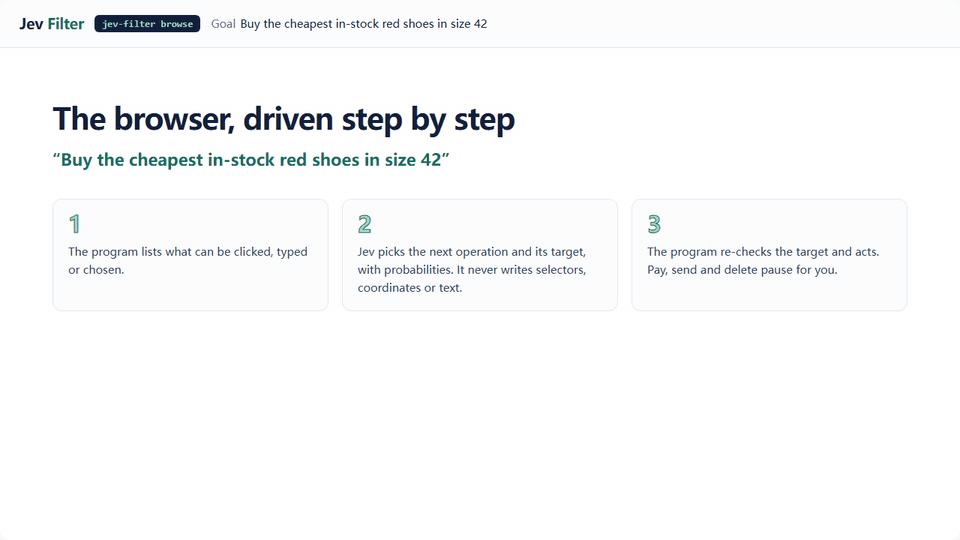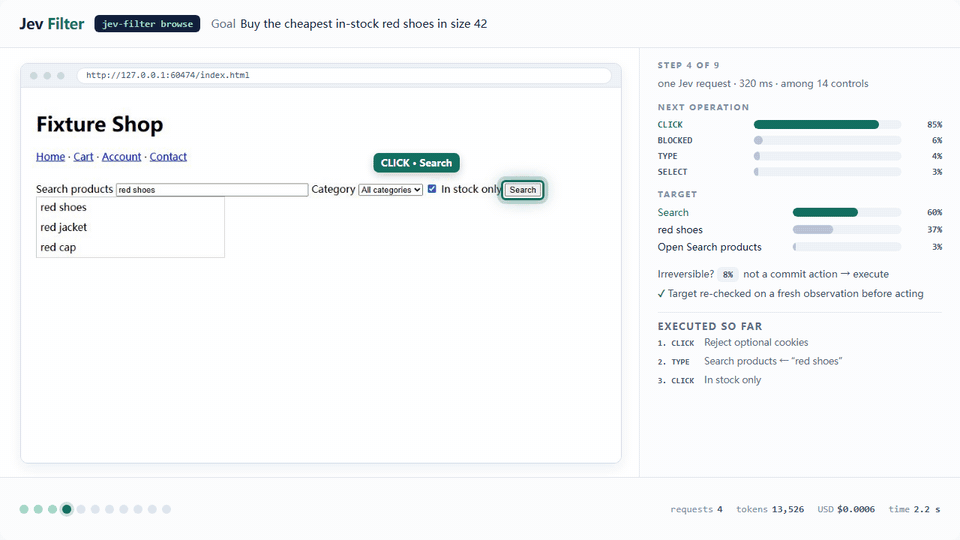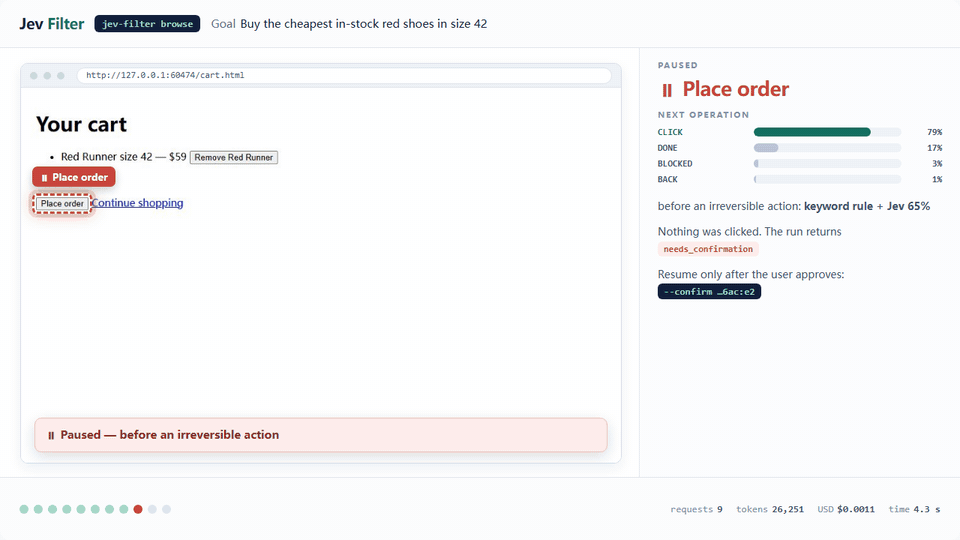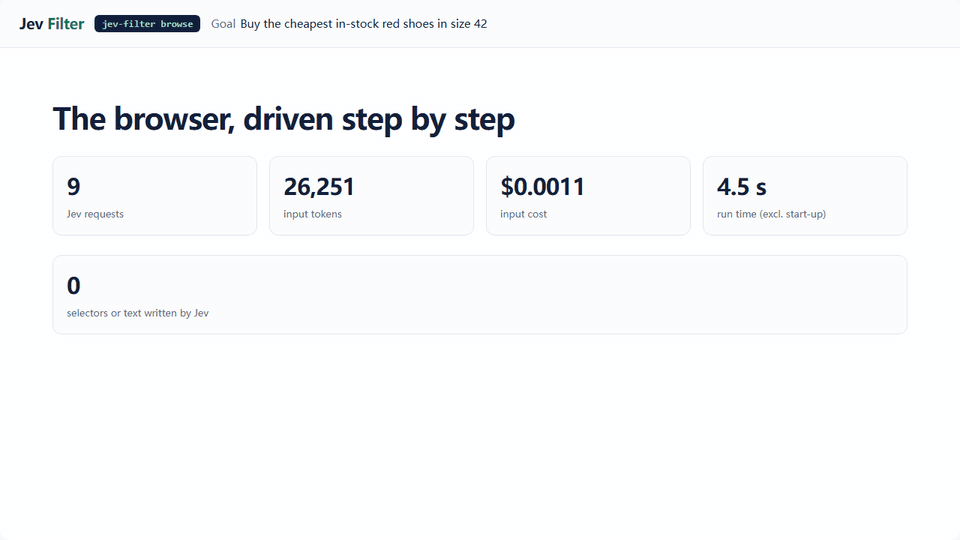
A real recorded run on the synthetic test shop, with Jev's actual probabilities · interactive replay: browser, desktop, survey · how it was recorded
Local savings dashboard
Configure a numeric-only local ledger, then run jev-filter stats dashboard (automatically selects a free port when 8765 is occupied) to automatically open a local browser dashboard showing estimated input-token reduction, USD input value, Jev cost and net value. Filter by model/date and export JSON or a standalone HTML snapshot. Unknowns and negative values stay visible. These are input-equivalent estimates, not invoice savings. See setup and measurement boundaries.
Why Jev Filter?
- Send less context to the primary agent. Filter before raw output enters the conversation; recover originals by ID. The fresh 48-run benchmark returned 88–97% less tool context. Evidence and trade-offs →
- Spend less on repeated Jev input. Automatic packing plus up to 30 concurrent requests. The public benchmark used 56.5% fewer input tokens and ran 32.4% faster than single-record parallel calls. Reproduce →
- Keep decisions inspectable. The agent controls the context, questions and output; missing facts remain
REVIEW. 8/8 exact fixture runs, plus three installed workflow acceptance checks. Public data · Integration evidence
Use it for many records + repeated semantic judgment + clear criteria. Use native tools for exact paths, IDs, selectors, calculations and short results. Keep open-ended reasoning and writing in your primary model.
Hosted execution: browser, desktop and data
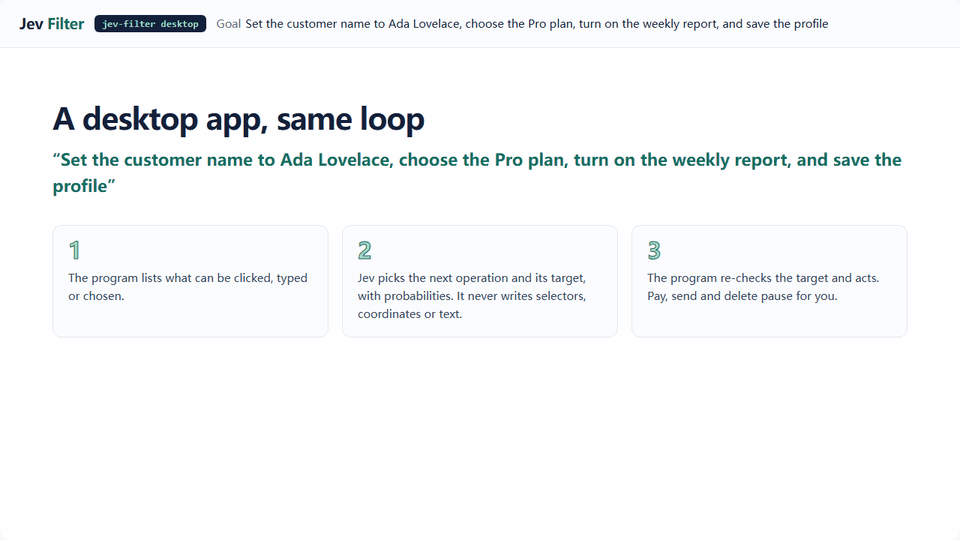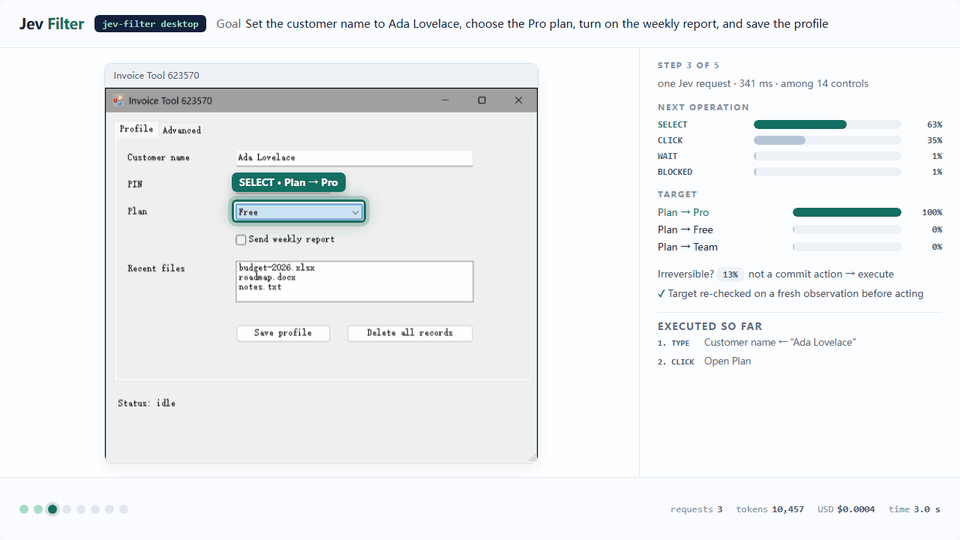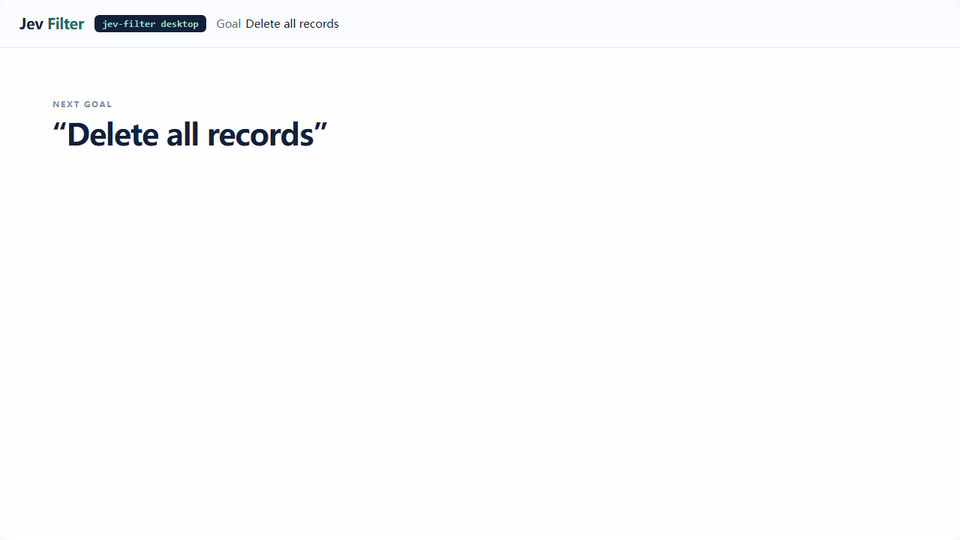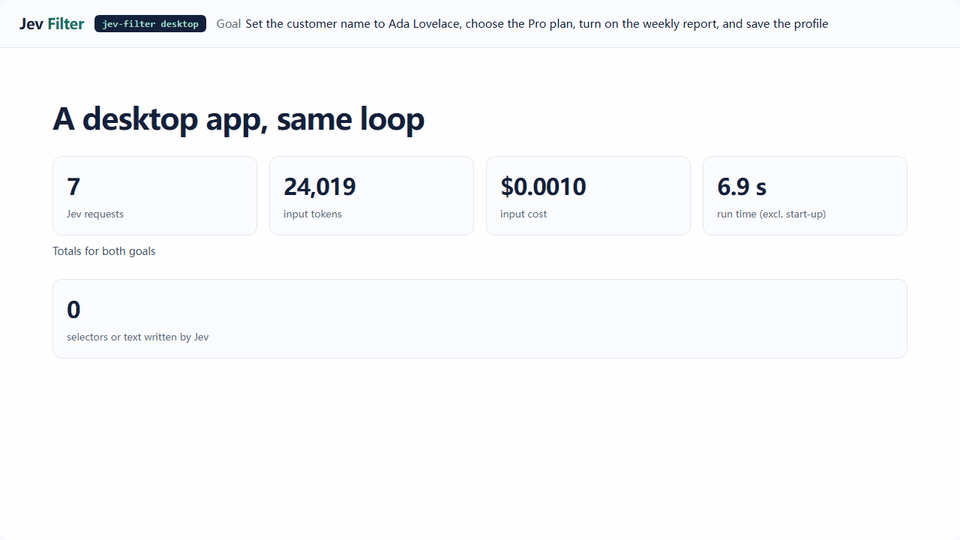
Jev chooses; the program acts. Each step observes the page or window, asks Jev one request for the next operation and its target among program-enumerated controls, re-checks the target and executes it. Jev never produces selectors, coordinates, commands or text. browse and desktop print one JSON packet, and only status: done (exit 0) is success. extract and survey exit 0 only when the result is ok and complete. A command that cannot start prints nothing on stdout and reports on stderr.
Drive a web page
jev-filter browse --url https://shop.example/ \
  --goal 'Buy the cheapest in-stock red shoes in size 42' \
  --value query='red shoes' --keep-open
It stops before the order button and hands the decision back (real output from the test shop, trimmed):
{
  "status": "needs_confirmation",
  "steps": 8, "requests": 9, "elapsed_ms": 3820,
  "usage": {"input_tokens": 26220, "output_tokens": 1678},
  "pending": {"label": "Place order", "role": "button"},
  "reason": "label_rule", "irreversible_probability": 0.67,
  "confirm_token": "0e5a2ab5892ab560:e2",
  "session": {"cdp_port": 61129, "target_id": "04C5D2DC…"},
  "trace": [{"step": 1, "operation": "CLICK", "action": "Reject optional cookies"},
            {"step": 2, "operation": "TYPE_TEXT", "action": "Search products", "value_key": "query"}, "…"]
}
After the user approves, resume the same tab. Only the confirmed action runs, then the verifier:
jev-filter browse --cdp-port 61129 --target-id 04C5D2DC… --confirm 0e5a2ab5892ab560:e2 \
--goal 'Buy the cheapest in-stock red shoes in size 42' \
--verify-text 'order has been placed' --close-browser
Pass values as a file when they need descriptions or must stay out of logs: --values values.json with {"email": {"value": "…", "description": "contact email", "sensitive": true}}. Attach to your own signed-in browser with --cdp-port, or use --transport camofox --session NAME. --dry-run returns the chosen control in pending and acts on nothing.
Pull structured data from a page
jev-filter extract --url 'https://shop.example/results?q=shoes' \
  --task 'In-stock products under $70' --analysis analysis.json
{"requirements": [
  {"id": "product",  "statement": "The record is a product row, not a heading or a link.", "expected": true},
  {"id": "in_stock", "statement": "The product is in stock.", "expected": true},
  {"id": "under_70", "statement": "The product costs less than $70.", "expected": true}],
 "fields": ["source_id", "text"]}
Tables become header-labelled rows. Of 14 records on the test page, 12 were excluded:
{"selected_ids": ["r1", "r3"], "review_ids": [], "complete": true,
 "excerpts": [{"source_id": "r1", "text": "Product: Red Runner | Category: shoes | Price: $59 | Rating: 4.4 | Availability: In stock"},
              {"source_id": "r3", "text": "Product: Blue Runner | Category: shoes | Price: $55 | Rating: 4.1 | Availability: In stock"}]}
Write each condition as its own requirement. Without --analysis the default question is only relevance, and the same page then also returned the $72 and $99 pairs.
Operate a desktop application
pip install 'jev-filter[desktop] @ git+https://github.com/apixly-ai/jev-filter.git@v0.3.0'
jev-filter desktop --list
jev-filter desktop --window '^Invoice Tool$' \
--goal 'Set the customer name to Ada Lovelace, choose the Pro plan, turn on the weekly report, and save the profile' \
--value name='Ada Lovelace' --verify-text 'saved Ada Lovelace'
The packet has the same shape as browse. A goal such as Delete all records ends as needs_confirmation before anything is deleted. Terminals, password managers and system settings are refused; creating ~/.jev-filter/STOP or parking the pointer in the top-left corner stops a run.
Survey thousands of records
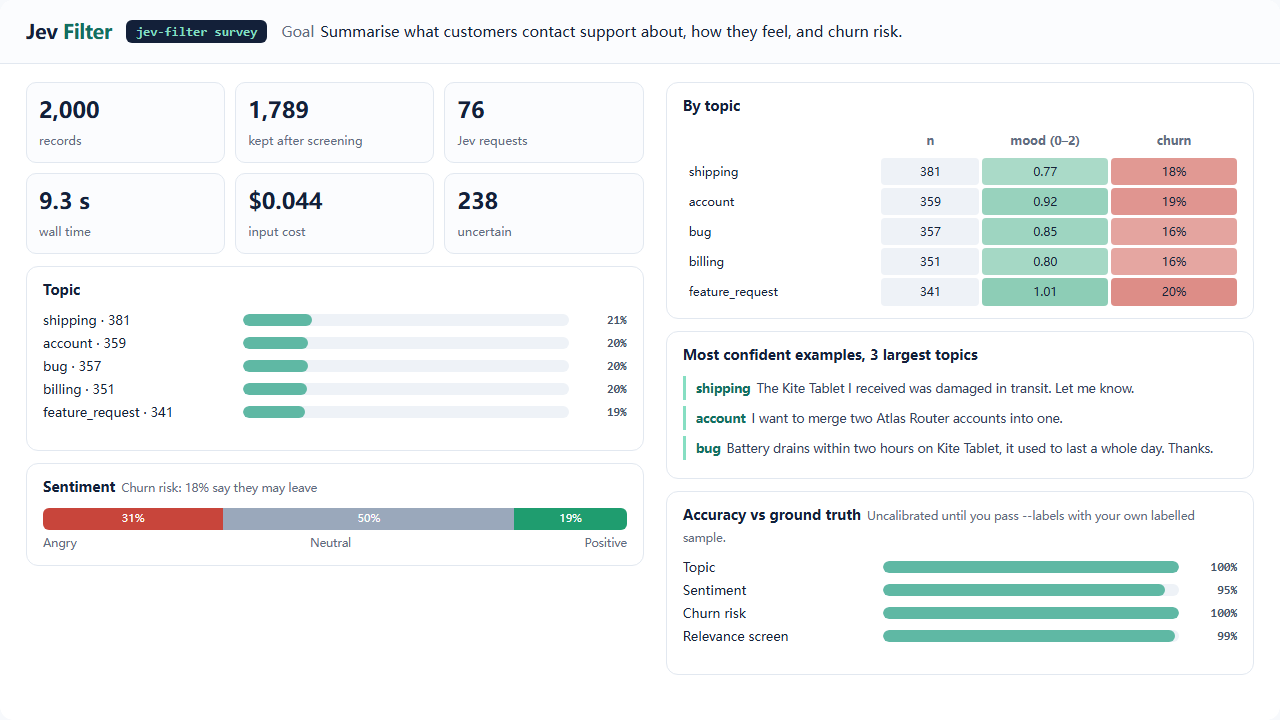
jev-filter survey --input tickets.jsonl --spec survey.json --dry-run
jev-filter survey --input tickets.jsonl --spec survey.json --format md
{"task": "Summarise what customers contact support about, how they feel, and churn risk.",
 "keep": ["product"],
 "screen": {"instructions": "The record is a genuine support request (not spam)."},
 "questions": {
   "topic": {"type": "choice", "instructions": "Main topic?",
             "criteria": {"billing": "…", "bug": "…", "feature_request": "…", "account": "…", "shipping": "…", "other": "…"}},
   "sentiment": {"type": "score", "instructions": "How does the customer feel?",
                 "criteria": ["Angry", "Neutral", "Positive"]},
   "churn": {"type": "noul", "instructions": "The customer threatens to cancel or switch."}},
 "group_by": ["topic", "product"]}
The report holds counts and shares, score levels, crosstabs, the most confident examples per group, uncertain and failed IDs, usage and cost. Jev writes no prose; your agent narrates from the report. On the 2,000 generated tickets above: 76 requests, 9.3 s, about $0.044 input. Against the generator's labels, topic was 100% and sentiment 95.2%. These records are easy by construction, so measure your own data with --labels.
From your agent
Keep the agent as the planner. It calls browse or desktop once per short sub-goal, with values and a verifier, and reads status. needs_confirmation and needs_value go back to the user. blocked with challenge or login_required goes back too. Skill reference: inputs, outputs and what to do per status →
What is measured
- Safe by construction. Pay/send/delete-like actions pause for confirmation; navigation stays on the start origin; passwords and CAPTCHAs are handed back, never handled; desktop runs refuse terminals and credential managers and stop on a STOP file.
- Measured on synthetic local fixtures with live Jev (three repetitions each, success checked by the program, not by the model):
| Browser (Camofox) | 5 | 15/15 | 0.7–13.7 s |
| Browser (Chromium via CDP) | 6 | 18/18 | 0.7–3.9 s |
| Desktop (Windows UIA + OCR) | 4 | 12/12 | 0.8–5.6 s |
| Survey (10,000 records) | 1 | topic 100.0%, sentiment 95.7% | 19.6 s, 375 requests, ~$0.22 input |
These are small synthetic tests with easy, template-generated records; they show the mechanics and costs, not open-web success rates. On real public websites the picture is weaker: in a read-only audit of 24 goals (48 runs), 16 of the 34 runs not stopped by a bot check, sign-in wall or provider outage reached the goal, and custom widgets were the weakest. Real-world audit → · Guide and limits → · Benchmark method →
Benchmarks
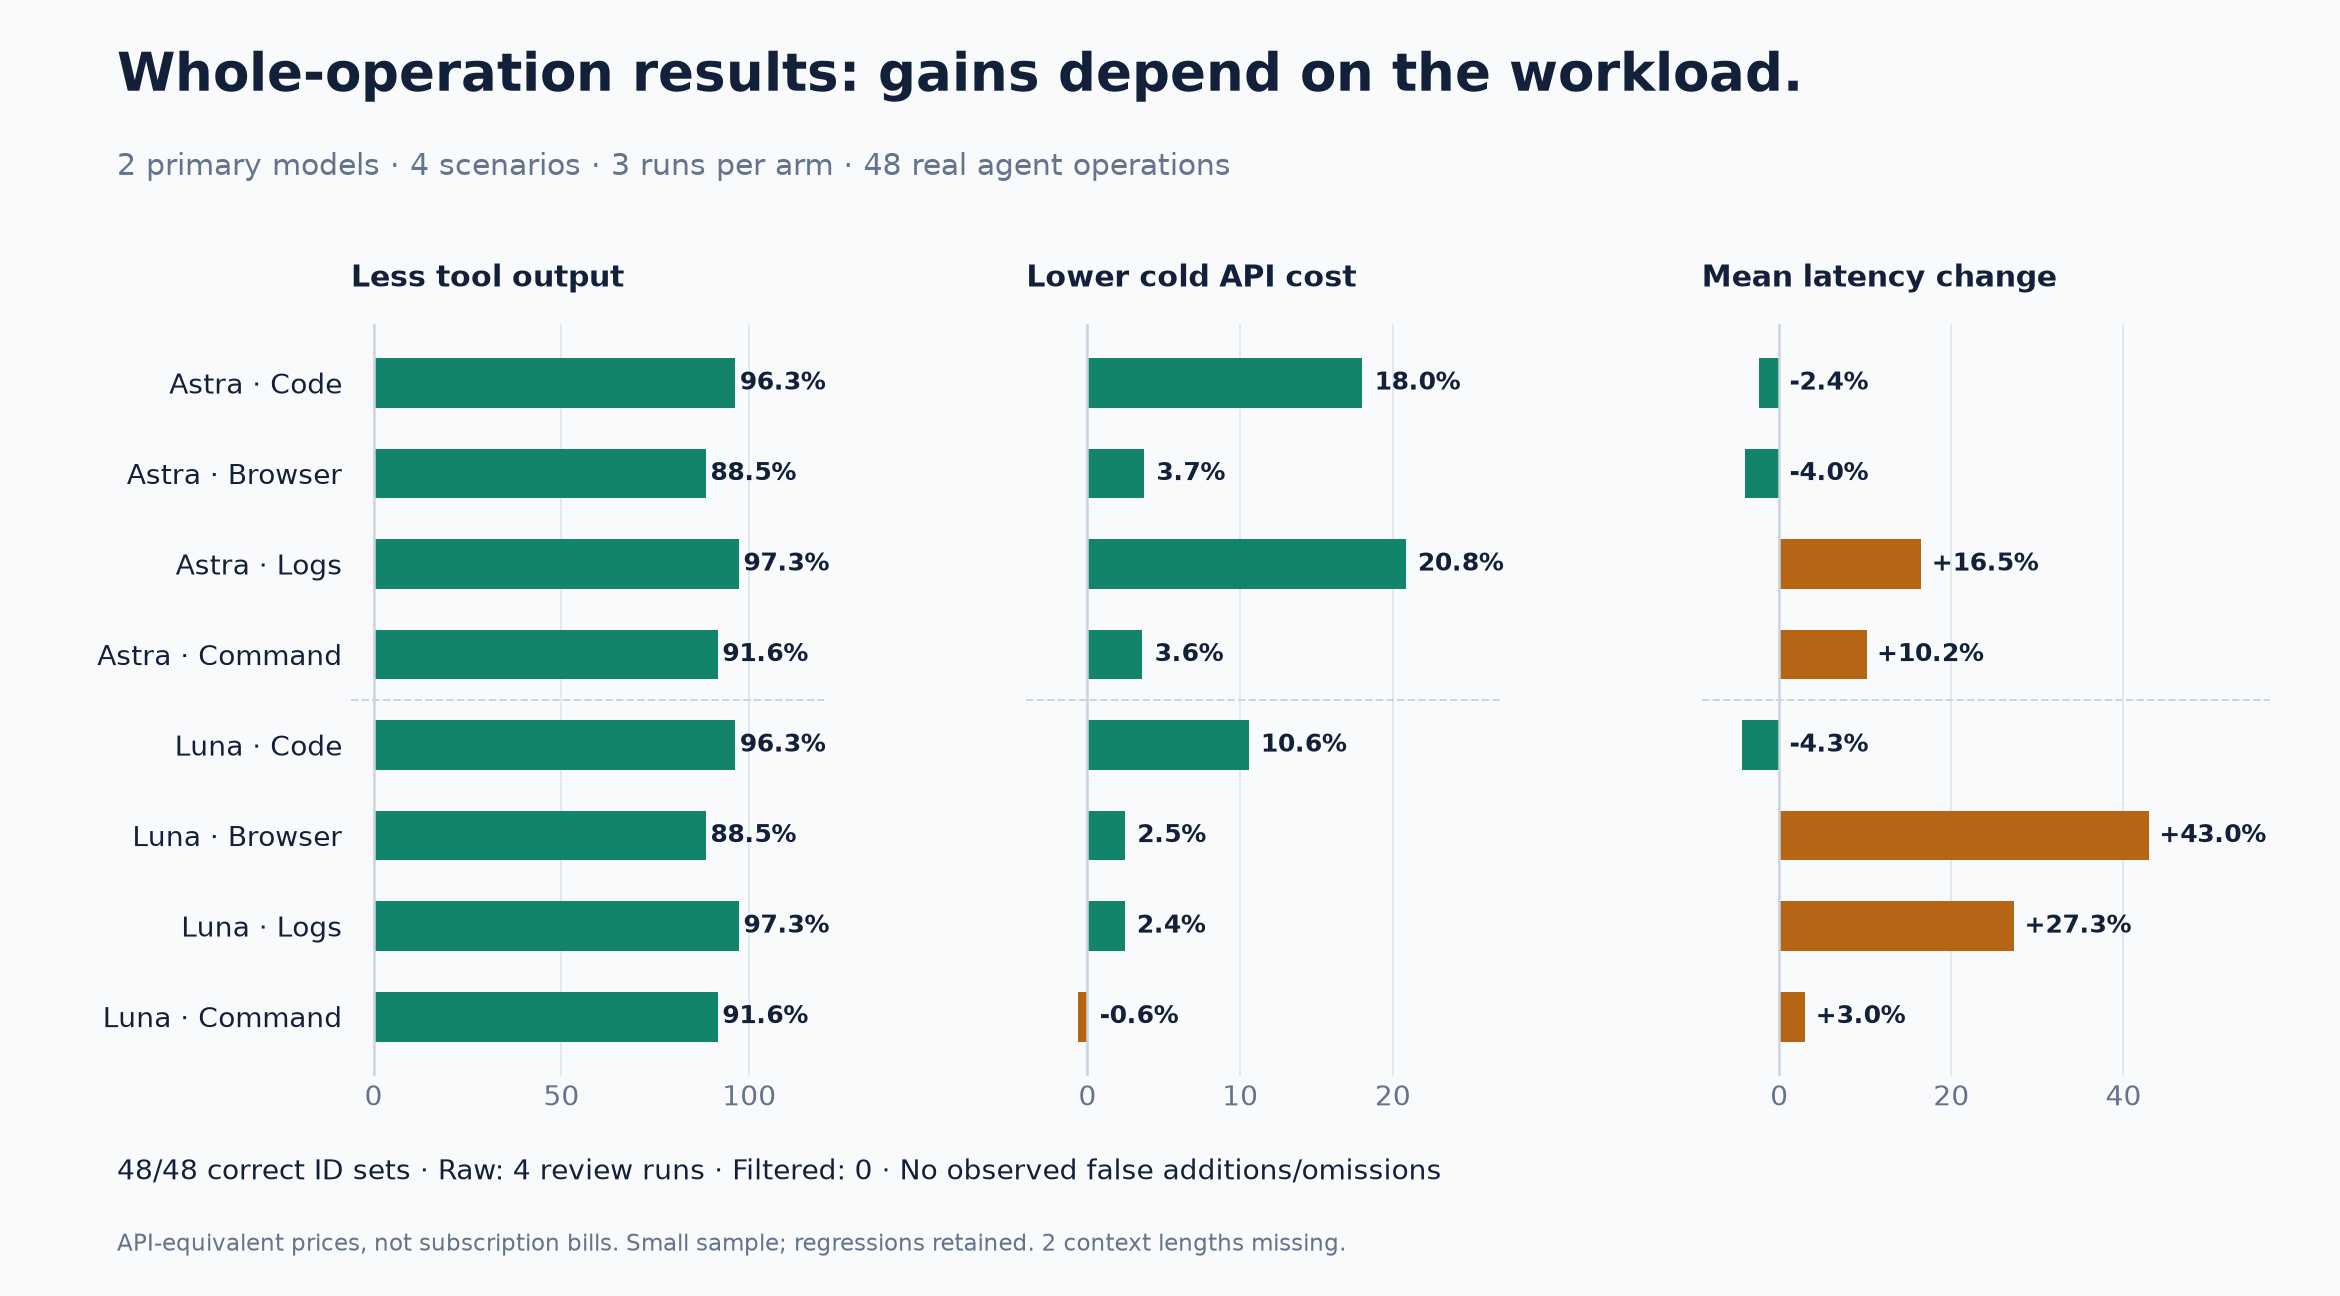
48 real agent runs: Astra and Luna, four scenarios, raw/filtered arms, three repetitions.
All runs selected the expected IDs. Four raw runs requested additional review; no filtered run did.
Returned tool context fell 88–97%. Cold API-equivalent cost ranged from 20.8% lower to 0.6% higher;
latency improved in some cells and regressed in others. These are small synthetic tests, not production guarantees.
Method and all results · Per-run JSON · CSV · Decision evidence
Why automatic batching and concurrency matter
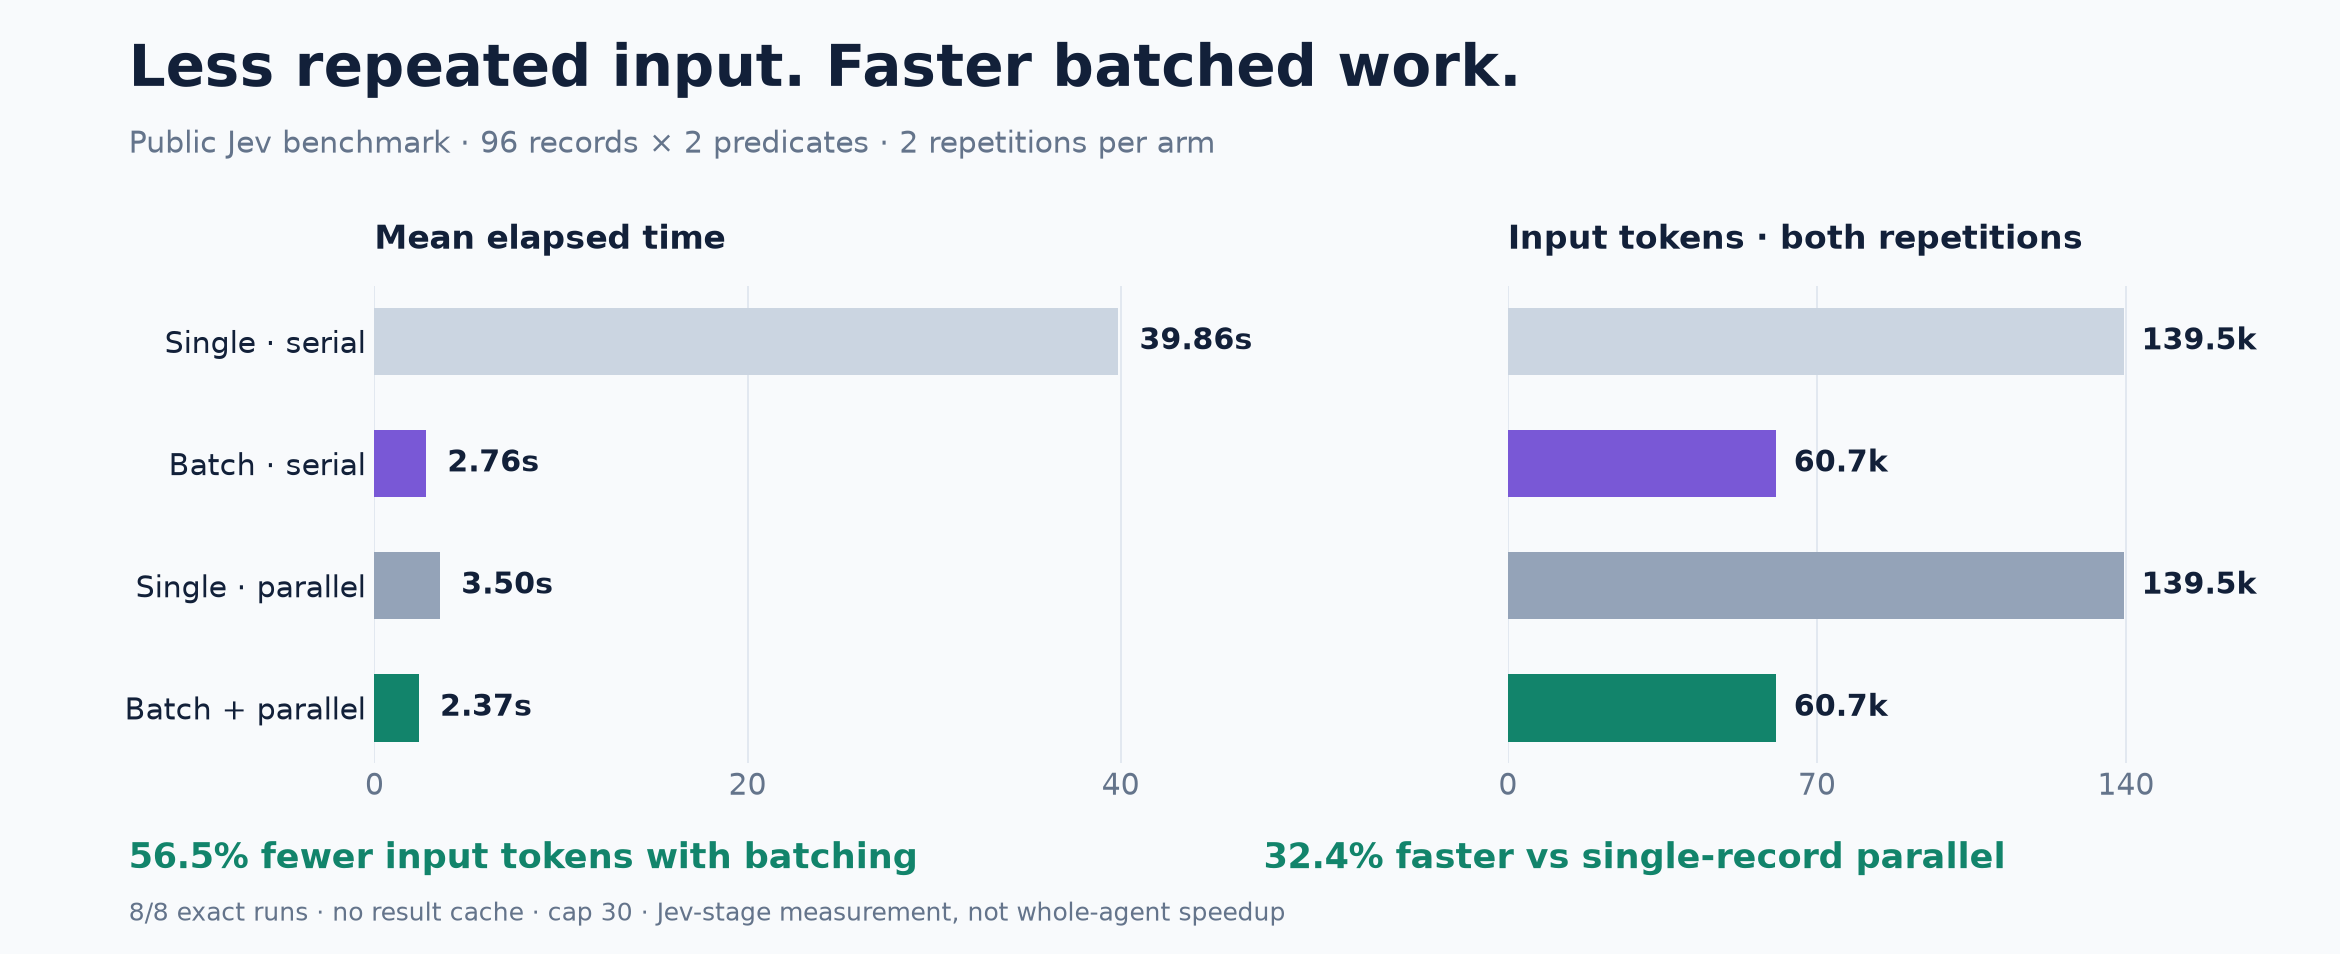
96 synthetic records × two predicates, two runs per arm. Batching used 56.5% fewer Jev input tokens;
batch + parallel was 32.4% faster than single-record parallel. This measures the Jev stage, not a whole agent task.
Raw results · Reproduce
Quick start
Node.js 22+ · macOS or Linux · no separate Python setup for the npm distribution. On Windows use WSL, or install the Python package natively from a GitHub Release wheel or pip install 'jev-filter[code] @ git+https://github.com/apixly-ai/jev-filter.git@v0.3.0' (Python 3.10+; rg on PATH for search; no PyPI package). A TypeSafe Jev API key is needed only for inference.
Install from npm:
npm install -g @apixly/jev-filter
jev-filter doctor
Set your key, then try a self-contained example from any directory:
export TYPESAFE_API_KEY='your-key'

jev-filter query --input - --mode choose \
  --task 'Choose the record showing a CURRENT unresolved DNS failure' <<'JSON'
[
  {"id":"a","text":"The previous DNS failure recovered; requests now succeed."},
  {"id":"b","text":"DNS lookup still fails; no connection can be established."}
]
JSON
Expected selection, with metadata omitted here:
{"selected_ids":["b"],"review_ids":[],"complete":true}
Small examples teach the interface; native tools are usually better for inputs this short. For real workloads, let the CLI collect the data itself:
jev-filter exec --task 'Find unresolved network failures' \
--analysis analysis.json -- your-collector --json
Start from a copyable analysis contract, then replace the collector. exec passes an argument array without an implicit shell. Read output and exit codes →
Connect your agent
The CLI works with any agent that can execute commands. It is not a separate agent or a required MCP server.
1. Install the skill. After a global npm install, for Codex:
mkdir -p ~/.codex/skills
cp -R "$(npm root -g)/@apixly/jev-filter/skills/jev-filter" ~/.codex/skills/
For another agent, copy the same skill into its supported skill directory. Claude Code and generic harness setup →
2. Give the agent this routing rule.
Use jev-filter when many records need a clear semantic judgment.
Pass the task, scope, exclusions, success criteria and sourced facts.
Keep collection → analysis → compact output inside one tool call.
Inspect unresolved IDs; do not repeat settled judgments or wrap an
existing Jev workflow again. Use native tools for exact or short work.
3. Supply context that changes the answer. Jev does not inherit the agent's chat. Put shared facts in context, record history on each record, and declare required fields. The agent controls questions, filtering, ranking and output projection. Complete integration guide → · Context contract →
Choose the right entrypoint
All flags and limits · Original evidence by ID · Architecture
Built for real use
We use Jev Filter in our own environment. Source annotation, Telegram maintenance planning and SRE routing retain their existing contracts and pass synthetic acceptance using real Jev calls. Private identities, credentials and production data are excluded from this repository.
- No result cache. Explicit context, bounded collection, retained failures and reported usage.
- Protected releases. Required CI/security checks, immutable release tags, checksums and build provenance.
- Portable core. Python library plus npm CLI distribution; automatic batching, maximum 30 requests in flight.
- Transparent boundaries. Inputs used for inference are sent to TypeSafe.
exec runs your command and is not a sandbox. Hosted execution runs only program-enumerated actions and pauses before irreversible ones. Security →
After one-time npm package trust setup, successful GitHub Releases automatically publish all five packages through OIDC and verify a fresh registry install. No long-lived npm token is stored. See publication and recovery.
Contribute
git clone https://github.com/apixly-ai/jev-filter.git
cd jev-filter
python -m venv .venv && . .venv/bin/activate
python -m pip install -e '.[code,dev]'
sh scripts/check.sh
npm test
Contributing · Development and releases · Governance · Changelog · Report a bug
Maintained by Apixly / JIA-ss · MIT · Independent of TypeSafe.



