

Security News
Deno Goes the Way of the Dinosaur
Cloudflare is acquiring Deno’s team, which will provide another year of bug fixes and security updates before ending support for the runtime.
By Sarah Gooding - Oct 16, 2026
@reportwright/pdf
Advanced tools
A streaming PDF writer for Node and browsers with no runtime dependencies: flat memory, PDF/A-1b to 3a, PDF/UA-1, Factur-X, embedded TrueType with Unicode text.
Create, comply, sign, light edit.
A streaming PDF library for Node and browsers with zero runtime dependencies.




Live demo · Playground · Benchmarks · Security model
Pages are written to your sink as they end, so memory stays flat however many pages you write: 20,000 pages hold about the heap that 1,000 do. It is the writer inside ReportWright, extracted, plus a hardened reader for merging, splitting, filling and signing existing files.
It does not render PDFs (use pdf.js or PDFium), and for heavy rewriting, repair or raw speed MuPDF, qpdf and pdfcpu are faster (see Benchmarks).
Install · Quick start · Features · Screenshots · Guide · Bundle size · Examples · Benchmarks · Options reference · Security model · Known limits · Public API and stability · Releasing · Changes
npm i @reportwright/pdf
ESM only. Node 20.16 or later, and modern browsers (the same dist/index.js; crypto comes from WebCrypto). Types are
included (index.d.ts). Optional, for complex scripts (Indic, Arabic) only: npm i harfbuzzjs.
// hello.mjs  →  node hello.mjs
import fs from 'node:fs';
import { createPdf } from '@reportwright/pdf';

const pdf = createPdf(fs.createWriteStream('hello.pdf'), { title: 'Hello' });
const page = pdf.addPage();                                       // A4, points, origin top-left
page.text('Hello, world', { x: 72, y: 72, font: pdf.standardFont('Helvetica-Bold'), size: 24, color: '#1f4e79' });
page.line(72, 104, 523, 104, { color: 0.6, width: 0.5 });
await page.end();                                                 // the page is written and freed
console.log(await pdf.end());                                     // { pages: 1, bytes: …, warnings: [] }
In memory instead of a stream: const bytes = await toBytes(async (pdf) => { … }, options).
| Area | What you get |
|---|---|
| Write | Text in the 14 standard fonts or embedded TrueType/OpenType (subset, kerned, any Unicode); text boxes with wrapping and alignment; JPEG/PNG images (alpha as a soft mask); Canvas-style vector paths, gradients, patterns, layers |
| Complex scripts | Devanagari, Bengali, Tamil, Telugu, Kannada, Arabic… through a HarfBuzz shaper you plug in (harfbuzzjs), text still extractable |
| Streaming | Each page is written and freed when it ends; flat memory for 20,000+ pages; timeoutMs and AbortSignal |
| Navigate | Links, named destinations, bookmarks, page labels, annotations |
| Forms | Every AcroForm field type with appearance streams; fill and flatten existing forms |
| Protect | AES-256 / AES-128 encryption with permissions |
| Sign | PAdES B-B / B-T signatures while streaming; incremental countersignatures that keep earlier ones valid |
| Comply | PDF/A-1b, 2b/2u/2a, 3b/3u/3a and PDF/UA-1 (veraPDF clean); Factur-X / ZUGFeRD / XRechnung invoices |
| Read and edit | Load (also damaged or encrypted files), merge, split, reorder, extract text, fill, stamp, saveIncremental |
| Bulk | One task over many files in worker threads, each with a heap cap and a per-file timeout; one bad file never stops the batch |
| Safe by default | No JavaScript or launch actions can be written; active content is stripped on read; every input is budgeted |
| Small | Zero runtime dependencies; one ESM file plus a lazily loaded fflate.js; TypeScript types included |
Page 1 of the examples, rendered by poppler (pdftoppm) on GitHub Actions straight from their output.
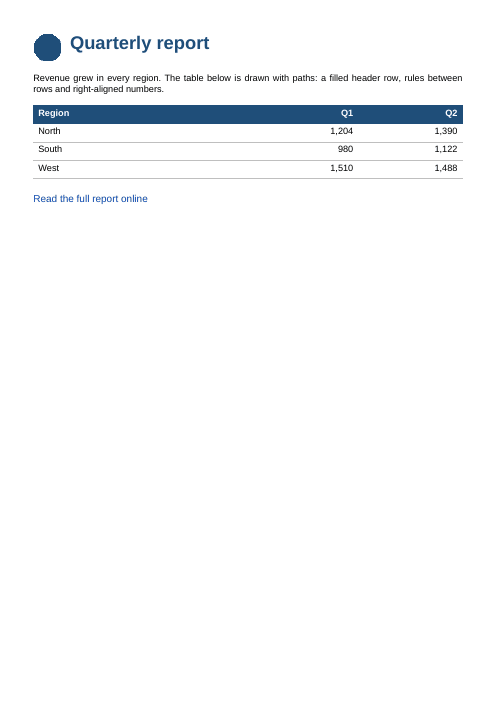 write.mjstext, image, table, link | 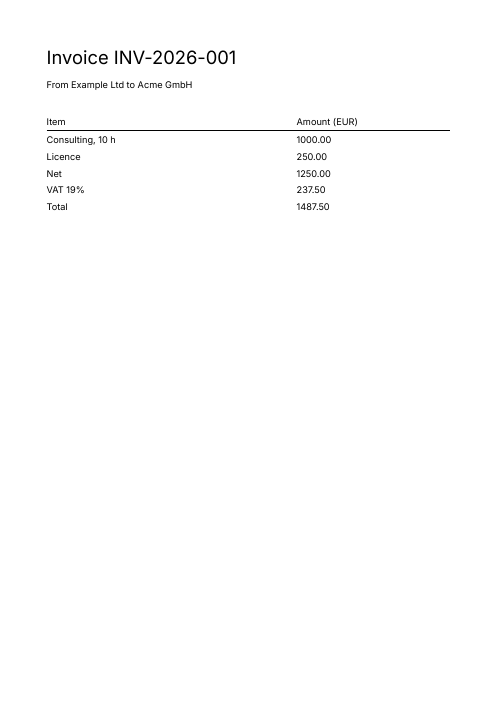 invoice-facturx.mjsFactur-X, PDF/A-3a | 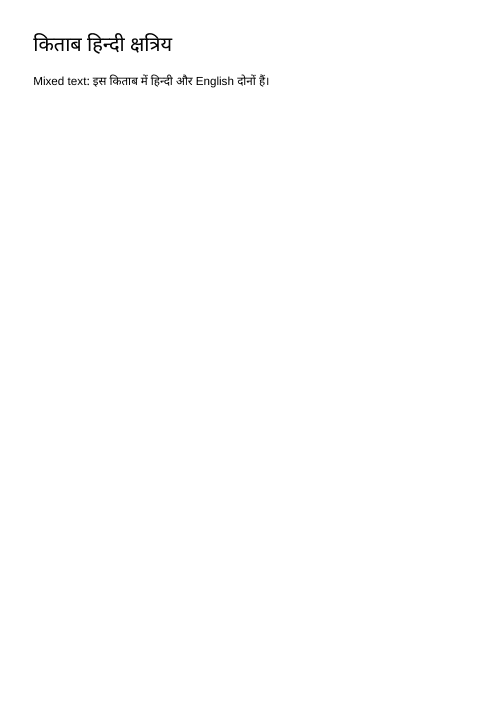 indic.mjsDevanagari via HarfBuzz |
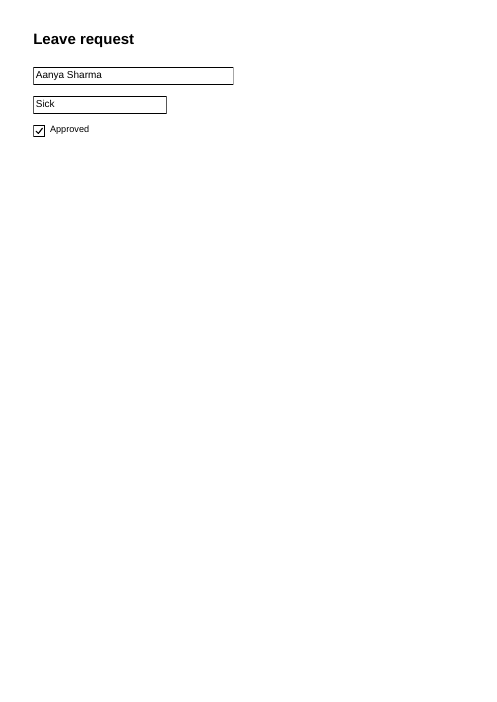 fill-form.mjsa form, filled | 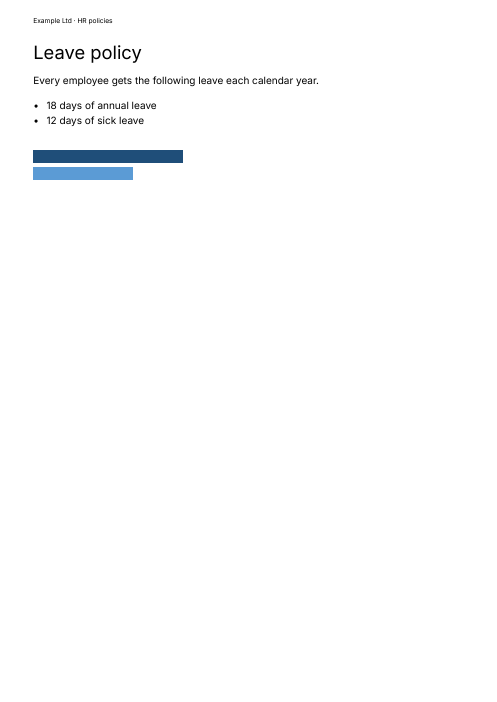 accessible.mjsPDF/UA-1 + PDF/A-2a, tagged |
Every snippet below is cut from a file in examples/, each of which was run and produces a PDF. The
examples import ../dist/index.js; in your code import @reportwright/pdf. They also ship in the package
(node_modules/@reportwright/pdf/examples/).
const pdf = createPdf(fs.createWriteStream('report.pdf'), { title: 'Quarterly report', author: 'Example Ltd' });
const regular = pdf.standardFont('Helvetica'), bold = pdf.standardFont('Helvetica-Bold');
const inter = await pdf.embedFont(fs.readFileSync('Inter-Regular.ttf'));          // subset, any Unicode
const logo = await pdf.embedImage(fs.readFileSync('logo.png'));                   // alpha becomes a soft mask

const page = pdf.addPage();
page.image(logo, { x: 40, y: 40, width: 32 });
page.text('Quarterly report', { x: 84, y: 44, font: bold, size: 22, color: '#1f4e79' });
const box = page.textBox(longText, { x: 40, y: 90, width: 515, font: inter, size: 11, align: 'justify' });
// box = { height, lines, overflow }: continue `overflow` in the next box or page
Tables are paths and text: there is no table primitive, so you control every rule and alignment.
const rows = [['Region', 'Q1', 'Q2'], ['North', '1,204', '1,390'], ['South', '980', '1,122']];
const cols = [40, 300, 430], right = 555, rowH = 22, top = 100 + box.height;
page.fill(page.path().rect(40, top, right - 40, rowH), { fill: '#1f4e79' });       // header band
rows.forEach((r, i) => {
  const y = top + i * rowH;
  r.forEach((cell, c) => {
    const font = i === 0 ? bold : regular;
    const x = c === 0 ? cols[c] + 6 : (cols[c + 1] ?? right) - 6 - font.widthOfText(cell, 11);   // right-align numbers
    page.text(cell, { x, y: y + 5, font, size: 11, color: i === 0 ? '#ffffff' : 0 });
  });
  if (i > 0) page.stroke(page.path().moveTo(40, y + rowH).lineTo(right, y + rowH), { stroke: 0.75, width: 0.5 });
});
await page.end();
await pdf.end();
Full file: examples/write.mjs (it also generates its PNG, so it needs no input files).
Pass a shaper to embedFont and conjuncts, reordered matras, Arabic joining and marks are drawn correctly; copied
and extracted text stays the source text, in logical order. The adapter for harfbuzzjs ships as
examples/harfbuzz-shaper.mjs.
import { harfbuzzShaper } from '@reportwright/pdf/examples/harfbuzz-shaper.mjs';   // needs: npm i harfbuzzjs

const bytes = fs.readFileSync('NotoSansDevanagari-Regular.ttf');
const hindi = await pdf.embedFont(bytes, { shaper: harfbuzzShaper(bytes) });
page.text('किताब हिन्दी क्षत्रिय', { x: 40, y: 40, font: hindi, size: 24 });
page.textBox('इस किताब में हिन्दी और English दोनों हैं।', { x: 40, y: 90, width: 400, font: hindi, fallback: [latin] });
node examples/indic.mjs NotoSansDevanagari-Regular.ttf. Right-to-left: { direction: 'rtl' } (there is no bidi
algorithm: split mixed-direction lines into runs yourself).
page.link(40, 300, 160, 14, { url: 'https://example.com/report' });              // http, https, mailto by default
pdf.destination('appendix', 2, { top: 40 });                                      // a named destination
page.link(40, 320, 160, 14, { dest: 'appendix' }, { alt: 'Go to the appendix' });
page.link(40, 340, 160, 14, { page: 2, fit: 'FitH', top: 0 });
pdf.outline([
  { title: 'Quarterly report', page: 1 },
  { title: 'Appendix', page: 2, level: 1 },                                       // level nests under the previous entry
]);
pdf.pageLabels([{ start: 0, style: 'r' }, { start: 2, style: 'D' }]);             // i, ii, 1, 2, …
import { toBytes, loadPdf } from '@reportwright/pdf';

const form = await toBytes(async (pdf) => {
  const font = pdf.standardFont('Helvetica'), page = pdf.addPage();
  pdf.form.textField('name', { page, x: 40, y: 80, width: 240, height: 22, font, tooltip: 'Full name', required: true });
  pdf.form.comboBox('type', { page, x: 40, y: 115, width: 160, height: 22, font, options: ['Annual', 'Sick', 'Unpaid'], value: 'Annual', tooltip: 'Leave type' });
  pdf.form.checkbox('approved', { page, x: 40, y: 150, width: 14, height: 14, tooltip: 'Approved by manager' });
  await page.end();
});

const doc = await loadPdf(form);
doc.fields;                                                        // [{ name: 'name', type: 'text', … }, …]
doc.fill({ name: 'Aanya Sharma', type: 'Sick', approved: true });  // appearances redrawn by the writer
const filled = (await doc.save()).bytes;

const flattened = (await (await loadPdf(form)).fill({ name: 'Aanya Sharma' }).flatten().save()).bytes;  // no AcroForm left
examples/fill-form.mjs writes form.pdf, filled.pdf and flattened.pdf. To
flatten while writing: createPdf(sink, { form: { flatten: true } }).
const bytes = await toBytes(build, {
  encrypt: {
    userPassword: 'open me', ownerPassword: 'full access',
    algorithm: 'aes-256',                                          // default; 'aes-128' for very old readers
    permissions: { print: true, copy: false, modify: false },      // each defaults to true
  },
});
const doc = await loadPdf(bytes, { password: 'open me' });         // doc.encryption.algorithm === 'aes-256'
examples/encrypt.mjs. RC4 is read, never written.
import { createPdf, loadPdf, nodeSigner } from '@reportwright/pdf';

const signer = nodeSigner({ key: fs.readFileSync('key.pem', 'utf8'), certs: fs.readFileSync('cert.pem', 'utf8') });
const pdf = createPdf(sink, { title: 'Offer letter', sign: true });
const page = pdf.addPage();
const hr = pdf.form.signature('hr', { page, x: 40, y: 700, width: 200, height: 40, tooltip: 'HR signature' });
pdf.form.signature('candidate', { page, x: 300, y: 700, width: 200, height: 40, tooltip: 'Candidate signature' });
await pdf.sign(hr, { signer, reason: 'Issued', location: 'Bengaluru', certify: 2 });
await page.end();
await pdf.end();                                                   // the signer runs here

// Countersign later: an incremental update, so the first signature stays valid.
const { bytes } = await (await loadPdf(signedBytes)).saveIncremental({ sign: { field: 'candidate', signer } });
examples/sign.mjs (make a test key with the openssl line at its top). Its output checks with
pdfsig: both signatures "Signature is Valid", the second "Total document signed". signer can be any async function
returning CMS bytes (an HSM, a cloud KMS: see cmsSigner); add timestamp for PAdES B-T.
const pdf = createPdf(sink, {
  title: 'Leave policy',
  tagged: { lang: 'en-GB' },                // PDF/UA-1: structure tree, title, embedded fonts
  pdfa: { part: 2, conformance: 'a' },      // or true (2b), { part: 1, conformance: 'b' }, { part: 3, … }
});
const font = await pdf.embedFont(fs.readFileSync('Inter-Regular.ttf'));
const page = pdf.addPage();
page.artifact({ type: 'Pagination', subtype: 'Header' }, () => page.text('HR policies', { x: 40, y: 20, font, size: 8 }));
page.tag('H1', () => page.text('Leave policy', { x: 40, y: 50, font, size: 22 }));
page.figure({ alt: 'Bar chart: annual leave 18 days' }, () => page.fill(page.path().rect(40, 180, 180, 16), { fill: '#1f4e79' }));
A Factur-X / ZUGFeRD invoice is PDF/A-3 with the CII XML attached:
const pdf = createPdf(sink, { title: 'Invoice INV-2026-001', pdfa: { part: 3, conformance: 'a' }, tagged: { lang: 'en' } });
// … draw the invoice from the same data as the XML …
await pdf.facturX(xmlBytes, { profile: 'EN 16931' });   // MINIMUM, BASIC WL, BASIC, EN 16931, EXTENDED, XRECHNUNG
examples/accessible.mjs (PDF/A-2a + PDF/UA-1) and
examples/invoice-facturx.mjs (self-contained PDF/A-3a invoice; factur-x.mjs
does the same from your own XML) both pass veraPDF with 0 failed rules (2a + ua1, 3a + ua1).
import { loadPdf, mergePdfs } from '@reportwright/pdf';

const a = await loadPdf(fs.readFileSync('contract.pdf')), b = await loadPdf(fs.readFileSync('annexure.pdf'));
const merged = await mergePdfs([a, b]);                            // { bytes, pages, stripped, warnings }

const all = await loadPdf(merged.bytes);
all.extractText();                                                 // every page, joined by \f
all.page(0).extractText();                                         // one page, in lines

for (let i = 0; i < all.pageCount; i++) {                          // split: one file per page
  fs.writeFileSync(`page-${i + 1}.pdf`, (await all.fork().reorder([i]).save()).bytes);
}

const doc = await loadPdf(merged.bytes);
doc.setInfo({ title: 'Contract (reviewed)' });
const { bytes } = await doc.saveIncremental();                     // the original bytes + an appended update
examples/merge-split.mjs. save() rewrites the file (and strips active content);
saveIncremental() appends (and refuses files with active content): see Security model.
import { bulk } from '@reportwright/pdf';

const files = fs.readdirSync('in').map((f) => fs.readFileSync(`in/${f}`));
const texts = await bulk(files, 'extractText', { workers: 4 });           // [{ ok: true, value } | { ok: false, error }]
const locked = await bulk(files, 'encrypt', { encrypt: { userPassword: 'u', ownerPassword: 'o' } });
const pages = await bulk(files, 'split');                                 // value: one Uint8Array per page
const joined = await bulk([[a, b], [c, d]], 'merge');                     // each input: the files to merge
Tasks are names (extractText, merge, split, encrypt; BULK_TASKS), never functions, so only bytes and plain
options cross to a worker. Results come back in input order; a file that fails (malformed, wrong password, over the
budget) gives { ok: false, error: { name, code, message } } and the batch goes on. Each worker's heap is capped
(memoryMb, default 512): a file that exhausts it kills only that worker, its item fails with E_WORKER, and a new
worker takes the next. workers defaults to os.availableParallelism() - 1. Node only: in browsers (no
node:worker_threads), and with workers: 1, the same tasks run one at a time in the calling thread, without the
heap cap. examples/bulk.mjs.
Workers stay warm (unref'd, so they never keep the process alive) for 2 s after a call, so the next call skips their
start-up; small files are sent several at a time (up to 8, or 256 KB, a worker). Each item has itemTimeoutMs (default 120000) in a worker: past it the worker is ended and the item fails with E_TIMEOUT; a failed item is never retried, so a batch of stuck or worker-killing files ends with each failing alone (workers is 1–64, memoryMb 16–16384; with workers: 1 there is no item timeout or heap cap). Pass signal to stop a call (or
AbortSignal.timeout(ms) for a time limit): its workers are ended and bulk rejects with the signal's reason. When
to use it: CPU-heavy items (encrypt, the text of long files) gain from the first call; cheap items on small files
(extractText or merge of 1–2 page files) gain only once the workers are warm: the first call pays ~25 ms a worker to
start them, so a one-off batch of under ~100 ms of work is quicker with workers: 1.
Measured on an Apple M2 (4 performance + 4 efficiency cores, 8 GB, busy laptop), Node 22, files made with
toBytes (small: 200 files of 2 pages, 0.4 MB in all; large: 20 files of 200 pages of text, 2.3 MB in all). Items/s
from the best of 3 calls in one process (warm), and the first call's ms (cold); results equal to workers: 1's
(encrypt: the same text once opened). Before: one worker started per call, one item a round trip.
| files | task | workers | items/s before | items/s now | first call ms before | now | peak RSS MB |
|---|---|---|---|---|---|---|---|
| small | extractText | 1 | 4762 | 4762 | 80 | 78 | 135 |
| small | extractText | 2 | 1923 | 5882 | 106 | 99 | 246 |
| small | extractText | 4 | 1754 | 6452 | 123 | 100 | 351 |
| small | merge | 1 | 2174 | 2128 | 137 | 136 | 148 |
| small | merge | 4 | 1299 | 3175 | 171 | 142 | 429 |
| small | encrypt | 1 | 284 | 288 | 733 | 738 | 171 |
| small | encrypt | 4 | 563 | 813 | 370 | 373 | 465 |
| large | extractText | 1 | 11 | 11 | 1906 | 1891 | 218 |
| large | extractText | 4 | 29 | 37 | 684 | 653 | 422 |
| large | merge | 1 | 143 | 135 | 224 | 220 | 176 |
| large | merge | 4 | 77 | 196 | 276 | 249 | 429 |
| large | encrypt | 1 | 149 | 155 | 213 | 212 | 181 |
| large | encrypt | 4 | 93 | 217 | 218 | 210 | 416 |
Gzip (gzip -9) of the built files in dist/. . is dist/index.js (writer and reader); ./write is dist/write.js
(writer only: createPdf, fonts, images, graphics, forms, standards, encryption, signing). fflate is a separate file
(dist/fflate.js) loaded on first use by either entry.
| entry | before (unminified) | after (minified) |
|---|---|---|
. (dist/index.js) | 166.8 KiB (170,811 B) | 133.4 KiB (136,583 B) |
./write (dist/write.js) | not exported | 85.0 KiB (87,080 B) |
fflate (dist/fflate.js) | 15.5 KiB (15,842 B) | 12.6 KiB (12,953 B) |
Import @reportwright/pdf/write when the code only writes PDFs: it leaves out the reader (loadPdf, mergePdfs) and
bulk. The two entries are separate bundles, so an app that imports both pays for the writer twice.
| file | what it shows | run |
|---|---|---|
write.mjs | text, a PNG, a table from paths, a link, bookmarks | node examples/write.mjs out.pdf |
indic.mjs | Devanagari shaped by HarfBuzz, Latin fallback | node examples/indic.mjs NotoSansDevanagari-Regular.ttf out.pdf |
harfbuzz-shaper.mjs | the harfbuzzjs shaper adapter (a module) | imported by indic.mjs |
fill-form.mjs | create, fill and flatten a form | node examples/fill-form.mjs outDir |
encrypt.mjs | AES-256 with permissions, read back | node examples/encrypt.mjs out.pdf |
sign.mjs | PAdES signature while streaming + countersignature | node examples/sign.mjs key.pem cert.pem out.pdf |
accessible.mjs | PDF/UA-1 + PDF/A-2a | node examples/accessible.mjs font.ttf out.pdf |
invoice-facturx.mjs | self-contained Factur-X PDF/A-3a invoice | node examples/invoice-facturx.mjs font.ttf out.pdf |
factur-x.mjs | Factur-X from your own CII XML | node examples/factur-x.mjs invoice.xml font.ttf out.pdf |
merge-split.mjs | merge, split, extractText, saveIncremental | node examples/merge-split.mjs outDir |
bulk.mjs | extractText and encrypt over many files in worker threads | node examples/bulk.mjs outDir |
p12-signer.mjs | a pdf.sign signer from a PKCS#12 (.p12) file through cmsSigner (needs node-forge) | imported by your code |
Run from node_modules/@reportwright/pdf (or the package folder of the repository).
The QA benchmark suite (qa/bench, GitHub Actions run 38317309719,
2026-10-12, the 1.0 release measurement) measures @reportwright/pdf 0.1.0-beta.15 from npm (the same code as 1.0.0:
only the version and doc comments changed) against the other libraries of each task on the same runner. Time is wall
time from process start to exit (warm invoice: in-process median). Each row is our time and peak memory next to the
fastest library in that row. The suite's verdicts: 8 PASS, 10 WARN, 2 FAIL of 20 rows. The losses are listed with
the wins.
| Task (size) | @reportwright/pdf | Fastest in the run | We are | Verdict |
|---|---|---|---|---|
| Writers: plain text pages (10) | 189 ms · 75 MB | printpdf (Rust) 77 ms | 2.46× slower, rank 3 of 13 | WARN |
| Writers: plain text pages (100) | 420 ms · 110 MB | fpdf (Go) 129 ms | 3.25× slower, rank 3 of 13 | FAIL |
| Writers: grouped report (100 rows) | 159 ms · 72 MB | fpdf (Go) 75 ms | 2.11× slower, rank 3 of 13 | WARN |
| Writers: grouped report (1,000 rows) | 240 ms · 79 MB | fpdf (Go) 102 ms | 2.35× slower, rank 3 of 13 | WARN |
| Writers: grouped report (10,000 rows) | 614 ms · 116 MB | fpdf (Go) 258 ms | 2.38× slower, rank 3 of 13 | WARN |
| Writers: invoice, cold process | 188 ms · 73 MB | printpdf (Rust) 75 ms | 2.49× slower, rank 4 of 13 | WARN |
| Writers: invoice, warm (50) | 8.5 ms · 130 MB | PDFsharp (.NET) 5.6 ms | 1.52× slower, rank 2 of 13 | WARN |
| Writers: Unicode (Hindi, Arabic, CJK) | 181 ms · 88 MB | fpdf (Go) 79 ms | 2.29× slower, rank 2 of 9 | WARN |
| Writers: images (6 MP PNG + 24 MP JPEG) | 991 ms · 197 MB | printpdf (Rust) 354 ms | 2.80× slower, rank 3 of 13 | WARN |
| Writers: PDF/A-2b invoice (veraPDF) | 185 ms · 73 MB | pdfkit (JS) 432 ms | 2.3× faster, rank 1 of 2 | PASS |
| Read: text of a 1,200-page PDF | 1206 ms · 120 MB | pdftotext (CLI) 795 ms | 1.52× slower, rank 3 of 14 | PASS |
| Read: 11 mixed real-world files | 208 ms · 79 MB | pdfium (CLI) 175 ms | 1.19× slower, rank 2 of 6 | PASS |
| Edit: merge 100 files | 182 ms · 80 MB | pdfcpu (Go) 68 ms | 2.67× slower, rank 8 of 15 | WARN |
| Edit: split 100 pages | 185 ms · 79 MB | pdfium (CLI) 110 ms | 1.68× slower, rank 9 of 15 | WARN |
| Edit: encrypt AES-256 | 136 ms · 76 MB | pdfcpu (Go) 44 ms | 3.07× slower, rank 5 of 10 | FAIL |
| Edit: incremental metadata change | 137 ms · 72 MB | PyMuPDF (Python) 159 ms | 1.16× faster, rank 1 of 6 | PASS |
| Edit: fill and flatten a form | 113 ms · 72 MB | PyMuPDF (Python) 154 ms | 1.36× faster, rank 1 of 7 | PASS |
| Edit: sign (PAdES/CMS, test certificate) | 111 ms · 72 MB | pdfbox (Java) 628 ms | 5.7× faster, rank 1 of 4 | PASS |
| Robustness: 25 fuzzed PDFs | 22 ok, 3 clean errors | no crash, hang or OOM | PASS | |
| Robustness: 6 hostile files | 4 ok, 2 clean errors | no crash, hang or OOM | PASS |
The small-edit rows (metadata, form, sign) are close to the harness's Node process start-up floor (about 110 ms), so they measure start-up as much as the work of each task.
In short: it is a fast JavaScript writer with flat memory, not the fastest PDF library. It is at or near the top on PDF/A, signing and small edits in this run, and 1.5–3× behind the native and Go writers on plain and report output. It is not the right tool for raw speed on repairs or large rewrites: MuPDF, qpdf and pdfcpu are faster there.
Medians from GitHub Actions run 38317309719 of ReportWright (ubuntu-latest, all libraries interleaved in one job), the same build as the Benchmarks table. Wall time from process start (warm invoice: in-process) · peak memory. Full write-up: JavaScript vs Python for PDFs.
| job | @reportwright/pdf | ReportLab | PyMuPDF | pypdf |
|---|---|---|---|---|
| Grouped report, 100 rows | 159 ms · 72 MB | 199 ms · 33 MB | 372 ms · 59 MB | — |
| Grouped report, 10,000 rows | 614 ms · 116 MB | 2378 ms · 45 MB | 13.17 s · 70 MB | — |
| Grouped report, 1,000,000 rows (older run 38108358497, 0.1.0-beta.12, not repeated for 1.0) | 29.07 s · 596 MB | 215.17 s · 1292 MB | 1358.32 s · 1279 MB | — |
| Invoice, single | 188 ms | 199 ms | 256 ms | — |
| Invoice, warm (50 in one process) | 8.5 ms · 130 MB | 8.7 ms · 34 MB | 54 ms · 60 MB | — |
| Extract text, 1,200 pages | 1206 ms | — | 1426 ms | 5424 ms |
| Split 100 pages | 185 ms | — | 177 ms | 198 ms (pikepdf 132 ms) |
| Fill and flatten a form | 113 ms | — | 154 ms | 175 ms |
Faster than the Python libraries at report scale (V8's JIT on the layout loop, typed arrays, a streaming writer that drops each page once written). ReportLab uses the least memory at every size and is within a few per cent on one-page documents; pikepdf (qpdf underneath) is faster at merge, split and encryption.
The sections below are the full API: every option of createPdf, the drawing methods, forms, encryption, signatures,
PDF/A levels and the reader. The most used:
| function | key options |
|---|---|
createPdf(sink, o) / toBytes(build, o) | title, author, creationDate, compress, metadata, pdfa, tagged, encrypt, sign, form.flatten, signal, timeoutMs, id (table) |
pdf.embedFont(bytes, o) | subset, shaper, textMapping (Fonts, Shaping) |
page.text / page.textBox | x, y, font, size, color, width, align, maxLines, fallback, direction, kerning (Text options) |
pdf.embedImage / page.image | colorSpace, maxDecodedBytes, compression / width, height, fit, opacity, alt (Images) |
page.fill / stroke | fill, stroke, width, dash, cap, join, opacity, blendMode, rule (Vector graphics) |
encrypt | userPassword, ownerPassword, algorithm, permissions, encryptMetadata (Encryption) |
pdf.sign(field, o) | signer, reason, location, name, certify, timestamp, subFilter, reserve (Signatures) |
loadPdf(bytes, o) | password, budget, timeoutMs, signal (Reading) |
doc.save(o) / mergePdfs(docs, o) | compress, keepActiveContent, encrypt, pdfa, keepStructure, creationDate |
doc.saveIncremental(o) | sign, keepActiveContent, allowFillAfterSigning, allowChangesAfterSigning |
PDF points (1/72 inch), origin at the top-left corner of the page, y growing downwards (as in CSS and canvas;
PDF itself counts from the bottom-left — the library converts). For page.text, y is the top of the line box:
the baseline sits at y + font.ascent * size.
createPdf(sink, options?)sink is a Node Writable, a WHATWG WritableStream, or any { write(bytes) } (its return value is awaited if it
is a promise). Back-pressure is honoured: a Node stream's false waits for 'drain'; a WritableStream waits for its
writer to be ready. pdf.end() ends a Node stream and closes a WritableStream; a plain { write } sink gets
close() called if it has one.
| option | meaning |
|---|---|
title, author, subject, keywords | document info, mirrored in the XMP metadata (every value escaped) |
metadata | true (default): an XMP metadata stream mirrors the info. false: the Info dictionary only, no XMP (a one-page invoice goes from 2.5 KB to 1.6 KB). Refused with pdfa or tagged: PDF/A and PDF/UA require the XMP |
creationDate | a Date (default: now). With the same input and date the output is byte-for-byte identical |
compress | true (default): content, fonts, object streams and the xref stream are Flate-compressed |
pdfa | true: PDF/A-2b (sRGB output intent bundled, XMP identification). Fonts must be embedded. { part, conformance, outputIntent }: a level (see PDF/A levels) and/or your RGB or CMYK output profile instead of sRGB (a CMYK intent allows CMYK colour and refuses RGB) |
tagged | { lang: 'en-GB' }: PDF/UA-1 — a structure tree (page.tag), title required, fonts embedded |
signal, timeoutMs | stop the export: pending and later calls reject with the signal's reason / a TimeoutError |
id | the file identifier (32 hex digits); default: a hash of the file's bytes (random when encrypting) |
encrypt | password protection, AES-256 or AES-128 (see Encryption) |
sign | true or { hash }: make the PDF signable with pdf.sign (see Signatures) |
pdf.standardFont(name) — one of the 14 standard fonts (Helvetica, Helvetica-Bold, Helvetica-Oblique,
Helvetica-BoldOblique, Times-Roman, Times-Bold, Times-Italic, Times-BoldItalic, Courier,
Courier-Bold, Courier-Oblique, Courier-BoldOblique, Symbol, ZapfDingbats). Not embedded; text is WinAnsi
(Latin-1 plus €, curly quotes, dashes…). Not allowed with pdfa or tagged.await pdf.embedFont(bytes, { subset, shaper, textMapping }) — a TrueType (glyf) or OpenType/CFF (.otf) font. Any Unicode
text (Identity-H with a ToUnicode map, so text can be copied and searched). TrueType embeds as FontFile2
(CIDFontType2); OpenType/CFF as FontFile3 /Subtype /OpenType (CIDFontType0; pdffonts says "CID Type 0C (OT)").
subset: true (default) keeps only the glyphs used, both kinds built in (TrueType: the glyphs used, their
components and .notdef are renumbered 0…n and only glyf loca head hhea hmtx maxp and the hinting tables
cvt fpgm prep are kept; the content still draws by the original glyph ID, through a /CIDToGIDMap stream, so
ToUnicode and widths are unchanged. CFF: unused glyphs' charstrings become
endchar, subroutines are kept, glyph IDs stay; a font using the deprecated seac accents embeds whole; a
CID-keyed CFF gets an identity charset so every reader maps its glyphs alike); false embeds the whole font; or a
function (font, codePoints, { glyphs }) => Promise<Uint8Array> (e.g. a HarfBuzz subsetter, which also
desubroutinises CFF) that must keep glyph IDs (its font is embedded as returned, /CIDToGIDMap /Identity, as
core callers that write their own fonts expect). shaper: see Shaping.
A variable font (an fvar table) is drawn at its default instance, which may be its thinnest weight (Noto Sans JP's
is Thin), with a warning naming the axes' values: for another weight, embed a static instance of it (fonttools
varLib.instancer, or hb-subset --instance).font.widthOfText(text, size, { kerning, characterSpacing, wordSpacing, horizontalScaling, direction }) — the width
text is drawn at (kerned, shaped, spaced); font.widthOf(text, size) — plain advances; font.lineHeight(size) —
ascent − descent + line gap (1.2 × size for standard fonts); font.ascent, font.descent (fractions of the size).Kerning is on by default: GPOS pair adjustment (formats 1 and 2, extension lookups too) of the kern feature,
else the legacy kern table (format 0). It is applied in measuring and drawing (TJ arrays); kerning: false turns it
off. Other GPOS positioning (marks, cursive) needs a shaper. The standard fonts are not kerned (the bundled AFM
metrics have no kerning pairs).
Characters a font has no glyph for are reported in pdf.end()'s warnings (standard fonts drop them; embedded fonts
draw the font's "missing" box, or drop it in PDF/A and PDF/UA, which forbid it).
const page = pdf.addPage({ width, height, cropBox, bleedBox, trimBox, artBox, rotate, userUnit }) (default A4).
page.number is 1-based. The boxes are [x, y, width, height] in the page's top-left space, inside the page (the
MediaBox); trimBox and artBox must lie inside bleedBox when both are given (pdfinfo -box shows them). rotate
(0, 90, 180, 270) turns the page clockwise as viewers show it: drawing coordinates stay those of the unrotated page
(top-left of the MediaBox), so a page added with { width: 842, height: 595, rotate: 90 } is drawn in landscape and
shown in portrait. userUnit (PDF 1.6, not in PDF/A-1) sets the default unit in 1/72 inch. A bad box throws and adds
no page.
page.text(str, { x, y, font, size = 12, color, … }) — one line (options below).page.textBox(str, { x, y, width, height, font, size, align, lineHeight, maxLines, ellipsis, … }) — paragraphs
(split at \n) wrapped by word, a word longer than the line broken inside; align: left (default; right for
direction: 'rtl'), right, center, justify (word spacing: Tw for standard fonts, TJ adjustments at spaces
for embedded fonts; a paragraph's last line is not stretched). maxLines ends the last line with … (... when
no font has it) when text is left; height stops at the last whole line that fits, without an ellipsis, so the
rest can go on in another box. Returns { height, lines, overflow } (overflow: the text not drawn, '' when it
all fit). No hyphenation. At most 10,000,000 characters and 100,000 lines a box (the rest is overflow); layout is
linear in the text it reads and stops once the visible lines are known.page.line(x1, y1, x2, y2, { color, width = 1, dash, opacity, blendMode }) — dash: [on, off].page.rect(x, y, w, h, { fill, stroke, width = 1, dash, opacity, fillOpacity, strokeOpacity, blendMode }) — fill, stroke or both (default: fill black). Opacity and blend mode work as in page.fill (an ExtGState inside q/Q; refused in PDF/A-1).page.link(x, y, w, h, target, { alt, highlight, border, quadPoints, allowSchemes }) — see Links below.page.tag(type, fn, options) — when tagged: what fn draws becomes a structure element of type
(P, H1…H6, Table, TR, TH, TD, L, LI, Link, Figure…). Tags nest. Anything drawn outside a tag is
marked as an artifact (decoration). Without tagged it just calls fn. See Tagged PDF.page.artifact({ type, subtype }, fn) — what fn draws is a typed artifact: type Pagination (with subtype
Header, Footer or Watermark), Layout or Page. Outside any tag.page.layer(layer, fn) — what fn draws belongs to a layer (see Layers).await page.end() — the page is compressed and written; nothing of it stays in memory.Text options (page.text and page.textBox):
| option | meaning |
|---|---|
kerning | true (default) / false |
characterSpacing | points after every glyph (Tc) |
wordSpacing | points at every space (Tw for standard fonts, whose space is the one-byte code 32; TJ adjustments for embedded Identity-H fonts) |
horizontalScaling | percent (Tz, default 100) |
rise | points the baseline is raised (Ts; negative lowers it): super- and subscripts |
renderMode | 0–7 or 'fill', 'stroke', 'fillStroke', 'invisible', 'fillClip', 'strokeClip', 'fillStrokeClip', 'clip' (Tr). The clipping modes add the glyphs to the clip until the enclosing page.restore(), so wrap them in save()/restore(). strokeColor, strokeWidth (default: color, 1) for the stroking modes |
rotate | radians, clockwise, about (x, y) (as page.rotate); any transform (page.rotate, scale, skew) applies to text too |
fallback | [fontB, fontC]: characters the font lacks are drawn in the first of these that has them, a run at a time (white space stays in the run it is in). Each run keeps its ToUnicode, so tagged PDFs stay extractable |
direction | 'rtl': the text is one right-to-left run (passed to the shaper; without one, glyphs reversed). A run of only right-to-left letters (Arabic, Hebrew) in a line is drawn right to left by itself. There is no Unicode bidi algorithm (UAX #9): mixed-direction text must be split into runs in visual order by the caller |
pdf.embedFont(bytes, { shaper }): text in that font goes through shaper(text, font, { direction, kerning }), which
returns the glyphs in visual order, in font units: [{ g, cl, ax, dx, dy }] (glyph ID, cluster = UTF-16 index of
its first character, x advance, offsets: what HarfBuzz's hb_shape gives). So Arabic, Indic and other complex
scripts draw correctly. The glyphs are drawn by ID with their advances and offsets (TJ adjustments, Ts for vertical
offsets); copied and extracted text is the source text, once, in logical order (checked with Acrobat-style
ActualText readers, poppler and pdf.js): a cluster of several glyphs (a conjunct, a reordered matra, a letter and its
dots) has its text on one glyph and WJ (U+2060) on the others, which are drawn after the run or inside an
/ActualText span, and a glyph that stands for different text in different places gets a code for each (a
CIDToGIDMap; a CFF font cannot, so there it gets an ActualText span). The shaper's output is checked (glyph IDs in
the font, finite numbers, clusters inside the text, at most 4 glyphs a character).
textMapping (left-to-right clusters in an ActualText span): 'carrier' (default) also maps the cluster's text on its
carrier glyph, which suits Firefox, pdf.js and search (MuPDF reads such a cluster twice); 'actualText' maps the
carrier to WJ so the text is only in the ActualText, which suits MuPDF/PyMuPDF and AI pipelines (pdf.js loses those clusters).
Either way the page renders correctly; what differs is each reader's text extraction: pypdf, like pdf.js, loses Indic
clusters in 'actualText' mode, and MuPDF reads Hindi and Kannada clusters twice in 'carrier' mode.
An adapter for harfbuzzjs v1 (npm i harfbuzzjs; not a dependency of this package). The same file ships in the package
as examples/harfbuzz-shaper.mjs:
import * as hb from 'harfbuzzjs';
function harfbuzzShaper(bytes) {
  const font = new hb.Font(new hb.Face(new hb.Blob(bytes)));     // positions in font units
  return (text, _font, { direction, kerning }) => {
    const buf = new hb.Buffer();
    buf.addText(text);                                           // clusters are UTF-16 indices
    buf.guessSegmentProperties();                                // script and language from the text
    buf.setDirection(direction === 'rtl' ? hb.Direction.RTL : hb.Direction.LTR);
    hb.shape(font, buf, kerning ? [] : [new hb.Feature('kern', 0)]);
    const pos = buf.getGlyphPositions();
    return buf.getGlyphInfos().map((g, i) => ({ g: g.codepoint, cl: g.cluster, ax: pos[i].xAdvance, dx: pos[i].xOffset, dy: pos[i].yOffset }));
  };
}

const bytes = fs.readFileSync('NotoSansDevanagari-Regular.ttf');
const hindi = await pdf.embedFont(bytes, { shaper: harfbuzzShaper(bytes) });
page.text('किताब हिन्दी', { x: 40, y: 40, font: hindi, size: 18 });
page.textBox(longText, { x: 40, y: 80, width: 300, font: inter, fallback: [hindi], align: 'justify' });
Colours (fills, strokes, text, gradient stops):
| form | colour space |
|---|---|
a gray level 0–1 | DeviceGray |
'#rgb', '#rrggbb', 'rgb(255, 128, 0)', 'rgb(100% 50% 0%)', [r, g, b] (0–1) | DeviceRGB |
cmyk(c, m, y, k) (import it) or [c, m, y, k] (0–1) | DeviceCMYK |
pdf.spotColor(name, alternate), or .tint(t) of it | Separation: a named ink, shown as its device alternate (gray, RGB or CMYK) at full tint, lighter tints towards white |
(await pdf.iccColorSpace(profileBytes)).color(...components) | ICCBased: a gray, RGB or CMYK ICC profile (its header is checked; /N comes from it) |
import { createPdf, cmyk } from '@reportwright/pdf';
const pantone = pdf.spotColor('PANTONE 185 C', cmyk(0, 0.91, 0.76, 0));  // written as /PANTONE#20185#20C
page.rect(40, 40, 100, 20, { fill: pantone });                          // full tint
page.rect(40, 70, 100, 20, { fill: pantone.tint(0.4) });
const p3 = await pdf.iccColorSpace(fs.readFileSync('Display P3.icc'));
page.text('Vivid', { x: 40, y: 100, font, color: p3.color(1, 0.2, 0.1) });
A spot colour's name is written exactly (PDF 1.7 §7.3.5: white space, delimiters, # and non-ASCII bytes as #xx, so
PANTONE 185 C is /PANTONE#20185#20C, which every reader and RIP decodes back to PANTONE 185 C; at most 127 bytes). One name has one definition per document. A gradient's stops share one colour
space: gray and RGB mix (as RGB), otherwise all CMYK, all tints of one spot colour, or all from one ICC space.
PDF/A needs device colour to match the output intent (ISO 19005-2, 6.2.4.3, as veraPDF checks): with the default
sRGB intent, CMYK colour (and CMYK spot alternates, CMYK gradients and CMYK JPEGs) throws a clear error; with
pdfa: { outputIntent: cmykProfile }, RGB colour throws instead. Gray, spot colours with a matching alternate and
ICC-based colours are allowed with either.
Paths are built as with the Canvas 2D API, in the same top-left, y-down space (so rotate and arc angles, in
radians, turn clockwise on the page, as in canvas). A path is not tied to a page; draw it with fill, stroke,
fillAndStroke or use it to clip.
const p = page.path()
  .moveTo(40, 40).lineTo(140, 40)
  .bezierCurveTo(160, 40, 160, 80, 140, 80).quadraticCurveTo(90, 120, 40, 80)
  .closePath();
page.fillAndStroke(p, { fill: '#cfe2f3', stroke: '#1f4e79', width: 2, join: 'round' });

page.fill(page.path().roundedRect(40, 140, 200, 60, [12, 12, 0, 0]), { fill: page.linearGradient(40, 0, 240, 0, [[0, '#1f4e79'], [0.6, '#5b9bd5'], [1, '#ffffff']]) });

page.save();                                   // transform, clip and styles until restore()
page.translate(300, 200).rotate(Math.PI / 6);
page.clip(page.path().arc(0, 0, 50, 0, 2 * Math.PI));
page.shade(page.radialGradient(0, 0, 0, 0, 0, 50, [[0, '#fff'], [1, '#c00']]));   // paint the clip area
page.restore();

page.svgPath('M10 300 h 80 a 20 20 0 0 1 0 40 h -80 z', { fill: '#e2efda', stroke: 0, dash: [4, 2] });
page.figure({ alt: 'Revenue up 12% on last year' }, () => page.fill(page.path().rect(40, 380, 120, 30), { fill: '#5b9bd5', opacity: 0.8 }));
page.path() → a Path: moveTo, lineTo, bezierCurveTo, quadraticCurveTo (written as a cubic), arc(x, y, r, start, end, ccw?), arcTo(x1, y1, x2, y2, r), ellipse(x, y, rx, ry, rotation, start, end, ccw?), rect,
roundedRect(x, y, w, h, radii) (one radius or canvas roundRect's 1–4 per-corner forms, scaled down when they do not
fit), closePath, svg(d). Each returns the path. At most 1,000,000 segments.
page.fill(path, o), page.stroke(path, o), page.fillAndStroke(path, o), page.svgPath(d, o) (fill, stroke or
both by which of fill/stroke you give; neither: filled black). Options:
| option | meaning |
|---|---|
fill, stroke (or color) | a colour, a gradient or a tiling pattern (default black) |
rule | 'nonzero' (default) or 'evenodd' |
width, dash, dashPhase | stroke width (default 1); dash lengths (at most 100, not all 0) and their phase |
cap, join, miterLimit | 'butt'/'round'/'square'; 'miter'/'round'/'bevel'; ≥ 1 (default 10) |
opacity, fillOpacity, strokeOpacity | 0–1 (opacity multiplies both) |
blendMode | any of the 16 PDF modes: Normal, Multiply, Screen, Overlay, Darken, Lighten, ColorDodge, ColorBurn, HardLight, SoftLight, Difference, Exclusion, Hue, Saturation, Color, Luminosity (or canvas names: 'color-dodge'…) |
Styles are per call (an option left out is its default), so draws do not leak into each other. Opacity and blend modes go into one ExtGState per distinct value in the document, and give the page a transparency group (as PDF/A-2 asks).
page.clip(path, rule?) — intersect the clip with the path until the enclosing restore().
page.save(), page.restore() — nest at most 1000 deep (27 in PDF/A, whose limit is 28). A restore() without a
save() throws; saves still open when the page ends are closed there, with a warning in pdf.end()'s result.
page.translate(x, y), page.rotate(angle), page.scale(sx, sy = sx), page.skew(ax, ay = 0),
page.transform(a, b, c, d, e, f) — as canvas; they apply to everything drawn after (text too) until restore().
page.linearGradient(x0, y0, x1, y1, stops, { extend }), page.radialGradient(x0, y0, r0, x1, y1, r1, stops, { extend }) — stops: [[offset, colour], …] or [{ offset, color }, …] (1–256, sorted, offsets clamped to
0–1, equal offsets make a hard stop; colours in one space: see Colours). Use as a fill/stroke, or page.shade(gradient) to paint the
current clip. Gradients follow the transform current when they are painted.
page.tilingPattern({ width, height, spacing }, (cell) => …) — cell has the page's drawing methods in the cell's
own top-left space (shapes, gradients, nested patterns; not text or links); cells repeat every width + spacing.
With no spacing the cell's /BBox is written 0.001 pt larger than the step: PDFium (Chrome, Edge) otherwise draws a
cell whose /BBox equals /XStep × /YStep one device pixel too far apart (a 20 pt cell every 21 pt at 72 dpi).
page.figure({ alt }, fn) — tagged PDFs: what fn draws is a Figure with that alt text (required). Graphics drawn
outside any tag are artifacts, so a tagged page of charts and rules stays PDF/UA-1 clean. Untagged, it just runs fn.
Gradients, patterns, fonts, pages, images, spot colours and ICC colour spaces are handles: only ones made by this document are accepted (a copy, a
hand-made { type: 'gradient', … } or one from another PDF throws). NaN, Infinity and numbers of 1e9 or more
throw before anything is drawn; malformed SVG path data throws a SyntaxError naming the position.
const photo = await pdf.embedImage(fs.readFileSync('team.jpg'));       // { width, height } in pixels
page.image(photo, { x: 40, y: 40, width: 200 });                        // height from the aspect ratio
page.image(photo, { x: 260, y: 40, width: 120, height: 120, fit: 'cover', alt: 'The team at the 2026 offsite' });
const logo = await pdf.embedImage(fs.readFileSync('logo.png'));         // alpha → a soft mask
for (const y of [400, 500, 600]) page.image(logo, { x: 40, y, height: 24, opacity: 0.6 });   // written once
await pdf.embedImage(bytes, { colorSpace, maxDecodedBytes, compression }) — a JPEG or PNG, written to the file at once as an image XObject;
returns a handle with width and height (pixels, after the EXIF orientation). colorSpace: an ICC colour space
(pdf.iccColorSpace) with the image's number of components, instead of the device space. maxDecodedBytes: the
decoded size allowed for a PNG that needs decoding (default 64 MB, 67,108,864 bytes). compression: the zlib level
for a PNG that is re-compressed (alpha or interlacing): 'default' is 6, or 3 above 2 megapixels (about half the
time for 2–3% more bytes on photos); 'fast' is 1; or a level 1–9. JPEGs and passed-through PNGs are not affected.
/Decode [1 0 1 0 1 0 1 0]. The EXIF orientation (1–8)
is honoured. 12-bit, lossless, hierarchical and arithmetic-coded JPEGs are refused./SMask); an 8-bit-or-less colour key a /Mask;
interlaced images are de-interlaced. Those are re-compressed. Other chunks (gamma, ICC, text, eXIf) are ignored.maxDecodedBytes)
for a PNG that needs decoding (alpha or interlacing). Such a PNG is decoded and re-compressed a row at a time: a
non-interlaced one is never held whole (memory: a strip of rows plus the compressed result), an interlaced one is
held once, de-interlaced. A JPEG is cut at the EOI that ends its image data and a passed-through PNG at the end of
its zlib stream: bytes appended after them are not embedded. Truncated or corrupt files, lying chunk or marker lengths, bad CRCs and
data that inflates past its header's size (a zip bomb) throw a clear error.page.image(img, { x, y, width, height, fit, opacity, alt }) — top-left (x, y) (default 0, 0). Only width or
height: the other keeps the aspect ratio; neither: one point per pixel. fit: 'fill' (default: stretch to the
box), 'contain' (all of the image, centred), 'cover' (fills the box, centred, cut to it). opacity 0–1. Tagged
PDFs: alt makes the image a Figure with that alternate text; without alt it is an artifact (decoration).embedImage called again with the same bytes (and the same options) in the
same document returns the same handle and writes nothing new (keyed by a SHA-256 of the bytes; Node's node:crypto,
else WebCrypto, else a fast hash confirmed byte for byte). A different option (colorSpace, maxDecodedBytes, compression)
embeds it again.A destination is a page and a fit, in the top-left space: { page, fit, left, top, right, bottom, zoom } where fit
is XYZ (left, top, zoom: 1 = 100%), Fit, FitH (top), FitV (left), FitR (left, top, right, bottom), FitB,
FitBH, FitBV. Without fit: XYZ when left, top or zoom is given, else Fit. page is 1-based or a page object
(it may not exist yet).
pdf.destination('appendix', 12, { top: 80 });                            // a named destination
page.link(40, 100, 120, 14, { dest: 'appendix' }, { alt: 'Go to the appendix' });
page.link(40, 120, 120, 14, { page: 3, fit: 'FitH', top: 200 }, { highlight: 'push' });
page.link(40, 140, 120, 14, { url: 'https://example.com/report' }, { border: { width: 1, style: 'dashed', dash: [3, 2], color: '#0645ad' } });
page.link(40, 160, 120, 14, { named: 'NextPage' });
page.link(x, y, w, h, target, o) — target: { url }, { page, …fit }, { dest: name } or { named: 'NextPage' | 'PrevPage' | 'FirstPage' | 'LastPage' }. Options: alt (what screen readers say; default the URL or
"Page n"), highlight (none, invert, outline, push), border ({ width, style: solid | dashed | beveled | inset | underline, dash, color }; default none), quadPoints (rectangles the link covers, e.g. a wrapped line),
allowSchemes.pdf.destination(name, page, fit) — written at the end to the catalog's Names tree as a balanced name tree (sorted,
64 a node, Kids and Limits when larger). Names are unique (a second definition throws), at most 1,024 UTF-8 bytes
and 100,000 a document; one that is used but never defined, or points past the last page, is a warning.No active content. A library that writes PDFs must not be a vector for it, so there is no way to write a
JavaScript, Launch, GoToR, GoToE, SubmitForm, ImportData or any other action: link targets and the open action are
destinations (plus the four navigation actions above), and anything else throws. URLs are limited to http, https
and mailto by default; allowSchemes: ['tel'] widens that per link, but javascript:, vbscript:, data: and
file: are never written, however spelled. A URL with a control character is refused (browsers drop them, which
hides schemes like java\tscript:); the rest is normalised by the WHATWG URL parser, percent-encoded (quotes,
parentheses and angle brackets too) and written as a hex string. Every caller's string (contents, titles, names) is a
hex string and every name is escaped, so no text can inject PDF syntax.
pdf.outline({ title, page | dest, level, open, color, bold, italic, …fit }) (or an array) — bookmarks. level
(0–63) nests: an entry is the child of the nearest one before it at a lower level. open: false shows it closed.
color: RGB or gray. At most 100,000 entries, titles of 4,096 characters.pdf.pageLabels([{ start, style, prefix, first }]) — labels viewers show for pages from the 0-based index start:
style D (1, 2, 3), r/R (i, ii / I, II), a/A (a, b / A, B) or none (the prefix alone), prefix, first (the
first number). Page 0 gets decimal labels when no range starts there.
pdf.pageLabels([{ start: 0, style: 'r' }, { start: 4, style: 'D' }, { start: 40, style: 'A', prefix: 'Appendix ' }]);
pdf.viewer({ … }) — hideToolbar, hideMenubar, hideWindowUI, fitWindow, centerWindow, displayDocTitle
(always true when tagged), direction (L2R/R2L), printScaling (None/AppDefault), duplex (Simplex,
DuplexFlipShortEdge, DuplexFlipLongEdge), pickTrayByPDFSize, numCopies (1–5); pageMode (UseNone,
UseOutlines, UseThumbs, FullScreen, UseOC, UseAttachments); pageLayout (SinglePage, OneColumn,
TwoColumnLeft, TwoColumnRight, TwoPageLeft, TwoPageRight); openAt: { page, …fit } (the open action: a
destination only). Unknown options throw.Each annotation method takes a box in the page's top-left space and returns a handle. Shared options: color (gray,
RGB or CMYK), contents (its text; required in tagged PDFs, where it is the description), author (/T),
modified (a Date), flags ({ print, hidden, noView, locked, readOnly, noZoom, noRotate, … }; default print).
Every annotation gets an appearance stream drawn by the library, so it looks the same in every viewer and passes
PDF/A (which needs one, and printed, visible annotations: PDF/A refuses hidden, noView or print: false).
const n = page.note(500, 60, { contents: 'Check this figure', author: 'Ada', icon: 'Comment', open: true });
page.note(525, 60, { contents: 'Done', author: 'Bo', replyTo: n });
page.highlight([{ x: 40, y: 100, width: 300, height: 16 }, { x: 40, y: 116, width: 120, height: 16 }], { contents: 'Key result' });
page.freeText('Sign here', { x: 40, y: 200, width: 120, height: 30, font, size: 12, background: '#fff8c4', border: { width: 1 } });
page.markup('Line', { x1: 40, y1: 260, x2: 200, y2: 300 }, { lineEndings: ['None', 'OpenArrow'], color: '#c00', contents: 'This one' });
page.stamp({ x: 380, y: 700, width: 160, height: 44, name: 'Approved', font });
page.attachFile(csvBytes, { x: 560, y: 60, name: 'figures.csv', mimeType: 'text/csv', description: 'The data' });
page.note(x, y, { icon, open, replyTo }) — a sticky note (Text), 20 × 20, not zoomed or rotated. icon: Comment,
Key, Note, Help, NewParagraph, Paragraph, Insert. replyTo: another annotation (/IRT).page.highlight(rects), page.underline, page.strikeOut, page.squiggly — text markup over one rectangle or
several (up to 10,000; QuadPoints are computed from them). A highlight multiplies, so the text shows through.page.freeText(text, { x, y, width, height, font, size, textColor, align, border, background, padding }) — text in
a box, wrapped and drawn with the package's own text.page.markup(type, geometry, { interior, lineWidth, dash, lineEndings }) — Square and Circle ({ x, y, width, height }), Line ({ x1, y1, x2, y2 }, lineEndings: [start, end]: None, Square, Circle, Diamond,
OpenArrow, ClosedArrow, Butt, ROpenArrow, RClosedArrow, Slash), Polygon and PolyLine ([[x, y], …]),
Ink ([[[x, y], …], …], strokes). color is the line, interior the fill. At most 100,000 points.page.stamp({ x, y, width, height, name, font }) — a standard stamp (Approved, Experimental, NotApproved,
AsIs, Expired, NotForPublicRelease, Confidential, Final, Sold, Departmental, ForComment, TopSecret,
Draft, ForPublicRelease) with its label drawn in font; or draw: (ap) => … to draw your own appearance on ap,
a page the size of the box.page.attachFile(bytes, { x, y, name, mimeType, description, created, modified, icon, allowTypes, allowArchives }) —
a FileAttachment annotation with the file embedded (/Params with its size, MD5 checksum and dates). Not in PDF/A-2,
which allows only PDF/A attachments (refused with an error). The file name is checked as an OS and a viewer would
read it: control, format and bidi characters (invoice\u202Efdp.exe), Windows-invalid characters and NTFS streams
(report.pdf:evil.exe), dot look-alikes, a leading dot, Windows device names and more than 255 UTF-8 bytes throw;
only passive types are allowed (pdf, images, text, csv, json, Office documents without macros, ics, vcf, eml…; not
rtf, msg or xml, which can carry embedded objects or external entities; zip with allowArchives), so anything else
needs allowTypes: ['ext'], by which you accept that type's risk (pdf.facturX embeds its checked XML itself);
slash look-alikes (docs/x.pdf), spaces other than U+0020 and runs of 3 spaces throw; double extensions
(invoice.pdf.scr) throw; a mimeType must be one of the extension's types (invoice.pdf as
application/x-msdownload throws; with no mimeType none is written; a type in allowTypes takes any MIME type, at
your risk). /F holds an ASCII form, checked with the same rules.Annot structure element (links a Link) with an object reference, pages
with annotations get /Tabs /S; veraPDF UA-1 and A-2b pass with notes, highlights, FreeText, shapes and stamps.pdf.form places interactive fields (AcroForm) on pages. Each field gets appearance streams for every state it can
show, drawn with the package's own text and graphics (NeedAppearances is false, so every viewer shows the same thing);
/DA names the field's font, and /DR is the shared Resources, which hold every font used. Each method returns a
field handle.
const font = await pdf.embedFont(interBytes);
const page = pdf.addPage();
const f = pdf.form;
f.textField('name', { page, x: 40, y: 40, width: 200, height: 22, font, value: 'Ada Lovelace', tooltip: 'Full name', required: true });
const address = f.group('address');                 // children are address.city, address.zip
address.textField('city', { page, x: 40, y: 80, width: 200, height: 22, font, value: 'Paris', tooltip: 'City' });
f.textField('pin', { page, x: 40, y: 120, width: 80, height: 22, font, comb: true, maxLen: 4, tooltip: 'PIN' });
f.checkbox('agree', { page, x: 40, y: 160, width: 14, height: 14, checked: true, value: 'Agreed', style: 'check', tooltip: 'I agree' });
f.radioGroup('size', { value: 'M', tooltip: 'Size', buttons: ['S', 'M', 'L'].map((v, i) => ({ page, x: 40 + i * 30, y: 190, width: 14, height: 14, value: v })) });
f.comboBox('country', { page, x: 40, y: 220, width: 150, height: 22, font, options: [['FR', 'France'], ['DE', 'Germany']], value: 'DE', tooltip: 'Country' });
f.listBox('langs', { page, x: 40, y: 250, width: 150, height: 60, font, options: ['English', 'French'], value: ['French'], multiSelect: true, tooltip: 'Languages' });
f.button('clear', { page, x: 40, y: 320, width: 80, height: 24, font, label: 'Clear', action: { reset: true }, tooltip: 'Clear the form' });
f.signature('sig', { page, x: 40, y: 360, width: 200, height: 40, tooltip: 'Sign here', lock: { action: 'All' } });
page, x, y, width, height (the widget's box), border ({ width, color }, default 1 pt
black; false: none), background, tooltip (/TU, also the accessible name: required in tagged PDFs),
readOnly, required. Text options (text, choice, button labels): font, fallback (fonts tried for characters
the font lacks), size (0, the default, is auto: 0 Tf in /DA, and the appearance uses the largest size up to 12
that fits), textColor, align (/Q: left, center, right). A value with a character no font has throws.textField — value, defaultValue, multiline, password (takes no value: readers must never store a password
in the file), comb with maxLen (1–1000 cells), maxLen, doNotSpellCheck, doNotScroll.checkbox — checked, value (the export value, the on state's name, default Yes; not Off), style
(check, cross, circle, square, diamond, star, drawn in the appearance), color (the mark's).radioGroup — one field, a widget per entry of buttons (each { page, x, y, width, height, value }, its own
export value), value (the selected one), noToggleToOff (default true), radiosInUnison, style (default
circle), color.comboBox (editable: any value; else the value must be an option's export value) and listBox (multiSelect:
several values, written with their indexes in /I). Options are strings or [export, display] pairs, written in the
given order (the Sort flag is never set); export values are unique; at most 10,000 options.button — a push button with a label (needs font) and/or an icon (an image from pdf.embedImage), a pressed
appearance (/D, pressedBackground) and an optional action: { reset: true } (ResetForm, every field),
{ reset: ['name', 'address.city', fieldHandle], exclude }, or { named: 'NextPage' | 'PrevPage' | 'FirstPage' | 'LastPage' }. Nothing else.signature — an empty signature field (a framed widget, /FT /Sig) with an optional lock ({ action: 'All' }, or
Include/Exclude with fields), to sign into later.pdf.form.group(name) — a parent field; its children are named name.child and written as a parent/kids tree
(at most 32 levels).createPdf(sink, { form: { flatten: true } }) draws every field's appearance into its page and
writes no AcroForm and no widgets: a filled form as a plain PDF (text extracts with pdftotext). In a tagged PDF each
flattened field is a Figure whose alternate text is the tooltip and the value.Form structure element (with the tooltip as /Alt) holding an object reference
to it; pages with fields get /Tabs /S. veraPDF UA-1 and A-2b pass with every field type, and flattened.action throws in PDF/A;
appearance dictionaries hold /N only (no pressed /D), a push button's as a one-state subdictionary.. (the hierarchy separator: use group), control, format, bidi or
separator characters, and is at most 256 characters; full names are unique (a duplicate throws). Every name, value,
option and tooltip is written as a hex text string, on-states and export values through the name writer./AA (additional actions), /JS, format, keystroke, validate or
calculate scripts, SubmitForm or ImportData: each field takes a fixed set of options, and anything else throws
(script-like keys with a message saying why). Calculation order (/CO) does not apply: it only orders calculate
scripts, and there are none.subset: false so a viewer has every glyph.A caller that draws its own appearances (pdf.core users) passes appearance: { normal } (a checkbox: { on, off })
of content-stream operators, written exactly, and da ('/F1 12 Tf 0 g', a font it registered with
core.resource('Font', …)): with both, no font is needed. Each field's widgetRef is its widget's object number,
and structParent puts a /StructParent on it for a structure tree of the caller's own.
const pdf = createPdf(sink, {
  encrypt: {
    userPassword: 'open me',          // '' (default): opens without a prompt, the permissions still apply
    ownerPassword: 'full access',     // left out: a random one (nobody can lift the permissions)
    algorithm: 'aes-256',             // default; 'aes-128' (V4/R4) for readers older than Acrobat 9
    permissions: { print: true, printHighQuality: false, modify: false, copy: false, annotate: true,
                   fillForms: true, accessibility: true, assemble: false },   // each defaults to true
    encryptMetadata: true,            // false: the XMP metadata stays readable
  },
});
/CFM /AESV3) is the default; AES-128 (V4/R4, /CFM /AESV2) is the option for old
readers. Every string and stream gets a fresh random 16-byte IV (crypto.getRandomValues), AES-CBC with PKCS#7
padding. R6 writes /U, /UE, /O, /OE and /Perms, and the catalog's Adobe extension level 8./Encrypt dictionary and the file ID are fixed at the start. The ID is therefore random (it can no longer be a
hash of the content) unless you pass id; and an encrypted file's bytes differ on every run anyway (random IVs
and salts), as they must.import { createPdf, nodeSigner } from '@reportwright/pdf';
const pdf = createPdf(sink, { sign: true }); // or { sign: { hash: 'SHA-384' } }
const page = pdf.addPage();
const field = pdf.form.signature('approval', { page, x: 40, y: 700, width: 200, height: 40 });
await pdf.sign(field, {
signer: nodeSigner({ key: privateKeyPem, certs: certificateChainPem }), // RSA, RSA-PSS (pss: true), ECDSA P-256/P-384
reason: 'Approved', location: 'Paris', name: 'A. Signer', contactInfo: 'a@example.com',
certify: 2, // optional DocMDP: 1 no changes, 2 form filling and signing, 3 also annotations
timestamp: async (signatureValue) => tokenFromYourTsa, // optional RFC 3161 TimeStampToken (PAdES B-T)
});
await pdf.end(); // the signer runs here
timestamp): CMS SignedData, detached, /SubFilter /ETSI.CAdES.detached (or
subFilter: 'adbe.pkcs7.detached'), with the signed attributes content-type, message-digest and ESS
signing-certificate-v2; signing-time only for adbe.pkcs7.detached (PAdES puts the time in /M)./ByteRange is known before
they are written: the digest of everything but /Contents goes to the signer, and its CMS fills /Contents
(hex, zero-padded to reserve bytes, default 16384; a CMS that does not fit is a clear error). In a browser
(no incremental SHA in WebCrypto) the file's bytes are held until the digest.signer is any async ({ digest, hash, subFilter, date, timestamp, signal }) => cmsBytes: an HSM, a cloud KMS or
node-forge. cmsSigner({ certs, keyAlgorithm, sign(bytes, hash) }) builds the CMS around a raw signature function
(what a KMS gives); nodeSigner({ key, certs, pss }) signs with node:crypto. A signer that does not answer is stopped by
signal/timeoutMs; when a timestamp is asked for, a CMS without one is refused.field is a signature field from pdf.form.signature, or { name, page, x, y, width, height } to make one. The
AcroForm gets /SigFlags 3. One signature a document (more need incremental updates)./Contents is not encrypted, as the spec requires) and with PDF/A-2b.An invisible signature: pdf.sign({ name: 'Signature1' }, { signer }) (no page, no size) is a zero-/Rect field in
the AcroForm only, so it works after every page is written (a document built through pdf.core); with page (still
open) it goes in that page's /Annots. A PKCS#12 (.p12/.pfx) file signs through cmsSigner:
examples/p12-signer.mjs (node-forge, which you install; not a dependency) gives p12Signer(bytes, password).
page.tag(type, fn, options) options: alt (/Alt), actualText (/ActualText: the text the element stands for),
expansion (/E: an abbreviation's expansion), lang (a language tag), id (/ID, unique, in the IDTree), and per
type: TH scope (Row, Column, Both); TH/TD headers (the ids of the TH cells that head it), rowSpan,
colSpan; L listNumbering (None, Disc, Circle, Square, Decimal, UpperRoman, LowerRoman,
UpperAlpha, LowerAlpha). Checked as you build: TR in Table/THead/TBody/TFoot, TH/TD in TR,
THead/TBody/TFoot in Table, LI in L, Lbl/LBody in LI; headings start at H1 and never skip a level
going down (H1 → H3 throws; going back up is fine), and a document uses H or H1–H6, not both (PDF/UA 7.4.2,
7.4.4; checked in the order you tag). A headers id no element has fails pdf.end().
page.artifact({ type: 'Pagination', subtype: 'Header' }, () => page.text('Quarterly report', { x: 40, y: 20, font, size: 8 }));
page.tag('H1', () => page.text('Sales', { x: 40, y: 50, font, size: 20 }));
page.tag('Table', () => {
  page.tag('THead', () => page.tag('TR', () => ['Region', 'Q1'].forEach((h, i) =>
    page.tag('TH', () => page.text(h, { x: 40 + i * 120, y: 90, font }), { scope: 'Column', id: `h${i}` }))));
  page.tag('TBody', () => page.tag('TR', () => ['North', '1,204'].forEach((v, i) =>
    page.tag('TD', () => page.text(v, { x: 40 + i * 120, y: 110, font }), { headers: [`h${i}`] }))));
});
page.tag('L', () => ['First', 'Second'].forEach((t, i) => page.tag('LI', () => {
  page.tag('Lbl', () => page.text(`${i + 1}.`, { x: 40, y: 140 + i * 18, font }));
  page.tag('LBody', () => page.text(t, { x: 60, y: 140 + i * 18, font }));
})), { listNumbering: 'Decimal' });
page.tag('P', () => page.tag('Span', () => page.text('CFO', { x: 40, y: 190, font }), { expansion: 'Chief Financial Officer' }));
pdfa: { part, conformance } (with outputIntent as before; pdfa: true is PDF/A-2b):
| level | what changes |
|---|---|
{ part: 1, conformance: 'b' } | PDF 1.4: %PDF-1.4, a classic cross-reference table and trailer (no object or xref streams), subset fonts carry a /CIDSet, OpenType/CFF fonts go in as their bare CFF (FontFile3 /CIDFontType0C). Refused: transparency (opacity, blend modes, highlights' Multiply, images with alpha), 16-bit images, layers, attachments, userUnit |
part 2, 'b' | as before |
part 2 or 3, 'u' | every character drawn must map to Unicode: a character the font (and its fallbacks) lacks throws instead of being dropped with a warning |
part 2 or 3, 'a' | 'u' plus tagged: tagged is required (use page.tag for the content) |
part 3, 'b'/'u'/'a' | embedded files allowed (pdf.attach, pdf.facturX), each with /AFRelationship and listed in the catalog's /AF |
Every level in this table passes veraPDF (--flavour 1b, 2b, 2u, 2a, 3b, 3u, 3a) with 0 failed rules on
a document with text, a table, a list, headings, images, links, a note, form fields, layers and attachments as the
level allows. PDF/A-1a is not offered (its structure rules predate PDF/UA; use 2a or 3a). Encryption is refused at
every level. PDF/X is not offered (no validator was available to check it).
await pdf.attach(csvBytes, { name: 'lines.csv', mimeType: 'text/csv', description: 'Invoice lines', relationship: 'Data' });
Document-level files, in the catalog's /Names /EmbeddedFiles tree (sorted, balanced: 64 a leaf), each with a file
specification (/F, /UF, /Desc, /AFRelationship) and an embedded-file stream (/Subtype the MIME type, /Params
with /Size, an MD5 /CheckSum, /CreationDate, /ModDate: default the document's date). pdfdetach -list shows
them. Options: name (checked like page.attachFile's: spoofing and look-alike characters, device names, an allowlist
of passive types, allowTypes/allowArchives to widen it), mimeType (must agree with the extension; required in
PDF/A-3), description, relationship (Source, Data, Alternative, Supplement, Unspecified; default
Unspecified in PDF/A-3), created, modified, maxBytes (refuse a larger file before it is copied; default and at
most 256 MB). At most 10,000 files; a name used twice throws. The bytes are written at the call (copied, so the checksum
is of what is written); nothing is held. PDF/A-1 and PDF/A-2 refuse attachments (PDF/A-2 allows only PDF/A files,
which cannot be checked here); in PDF/A-3 every file is listed in /AF.
const pdf = createPdf(sink, { title: 'Invoice 2026-001', pdfa: { part: 3, conformance: 'b' } });
// … draw the invoice …
await pdf.facturX(ciiXmlBytes, { profile: 'EN 16931' });   // MINIMUM, BASIC WL, BASIC, EN 16931, EXTENDED, XRECHNUNG
Needs PDF/A-3 (b, u or a). The XML is embedded as factur-x.xml (xrechnung.xml for XRECHNUNG), MIME
text/xml, /AFRelationship /Data for MINIMUM and BASIC WL (they are not a full invoice) and /Alternative for the
others, and listed in /AF; the XMP gets the fx: properties (DocumentType INVOICE, DocumentFileName, Version 1.0, ConformanceLevel the profile) with the PDF/A extension schema that describes them (Factur-X 1.0.07; ZUGFeRD 2.1
and later use the same). version is '1.0' (the only one). One invoice a document.
The XML is data: it is never handed to an XML parser. A size-capped (10 MB), linear scan refuses any DOCTYPE,
ENTITY, ELEMENT or ATTLIST declaration (no entity can expand), requires UTF-8, checks that the root element is
CrossIndustryInvoice and that its GuidelineSpecifiedDocumentContextParameter ID names the profile given (BASIC
needs urn:cen.eu:en16931:2017#compliant#urn:factur-x.eu:1p0:basic, and so on; XRECHNUNG any
…#compliant#urn:xeinkauf.de:kosit:xrechnung_ version). It does not validate the invoice: run the Factur-X XSD and
Schematron (or the KoSIT validator for XRechnung) before embedding. Checked: veraPDF A-3b/3u/3a with 0 failed rules,
pdfdetach, and the factur-x Python package (akretion) extracting factur-x.xml from the PDF and passing its XSD.
examples/factur-x.mjs writes a tagged PDF/A-3a invoice.
const notes = pdf.layer('Reviewer notes', { visible: false });
page.layer(notes, () => page.text('Check this total', { x: 400, y: 300, font }));
pdf.layer(name, { visible = true, printable = visible, locked = false }) makes an optional content group;
page.layer(layer, fn) puts what fn draws (synchronously; save()/restore() must balance inside) into it, as
/OC … BDC … EMC; layers nest (at most 32 deep). The catalog gets /OCProperties with every layer in /OCGs and the
default configuration /D (/Name, /Order listing every layer, /ON, /OFF, /Locked). visible and
printable differing makes a screen-only or print-only layer (/Usage and the /AS auto-states); PDF/A forbids
/AS, so there they must agree. Not in PDF/A-1 (refused). At most 10,000 layers.
await pdf.end() — ends open pages, writes fonts, outline, metadata and the cross-reference stream; resolves to
{ pages, bytes, warnings }.pdf.core (typed PdfCore in index.d.ts) is the layer every feature module is written on, for a caller that writes
its own content streams and objects beside the Pdf methods (the ReportWright engine does). Not covered by semver in
0.x; ARCHITECTURE.md ("Extension points") has the details.
const pdf = createPdf(sink);
const { core } = pdf;
const n = core.reserve(); // an object number, written later
await core.write(n, '<< /Type /ExtGState /ca 0.5 >>'); // small objects go into object streams
const gs = core.resource('ExtGState', `${n} 0 R`); // a name in every page's shared Resources
core.catalog('PageLabels', '<< /Nums [0 << /S /r >>] >>');
core.onFinish(async () => {
  /* runs at pdf.end(), after the last page, before the fonts and the catalog */
});
reserve(), write(n, dict, stream?), writeStream(n, dict, raw), writeBig(n, head, parts, tail),
object(dict, stream?) — objects; a stream's bytes are already filtered (/Length is added).resource(kind, value, name?), resourcesRef — the shared Resources dictionary.imageResource(image) → { name, ref, alpha, orientation } — an image from pdf.embedImage for your own content
stream: q w 0 0 h x y cm <orientation> cm /<name> Do Q (with alpha, give the page a transparency /Group).catalog(key, value), onFinish(fn), info, xmp — the end of the document; info set to a dictionary's text
replaces the Info made from the options.pageRef(i), pageHeight(i), pageCount, warn(msg), serial(fn), tags — pages, warnings, ordering, tagging.import { loadPdf, mergePdfs } from '@reportwright/pdf';
const doc = await loadPdf(bytes, { password, budget: { maxDecoded: 256 << 20 }, timeoutMs: 10_000, signal });
doc.pageCount; doc.info; doc.xmp; doc.pdfa; // { part: 3, conformance: 'a' } or null
doc.page(0).extractText(); // content order, in lines
doc.outlines; doc.fields; doc.attachments; doc.signatures;
doc.copyPages(other, [0, 2], { at: 1 }).removePages([4]).movePage(0, 3);
doc.page(0).rotate(90);
doc.page(0).draw((p, { fonts }) => p.text('DRAFT', { x: 200, y: 400, font: fonts.f, size: 60, color: '#c00000' }), { fonts: { f: 'Helvetica-Bold' } });
doc.fill({ 'name': 'Ada', 'agree': true, 'size': 'L', 'tags': ['a', 'b'] }, { font: ttfBytes });
doc.setInfo({ title: 'Signed copy' });
const { bytes, stripped, warnings } = await doc.save({ encrypt: { userPassword: 'pw' } });
const merged = await mergePdfs([a, b, c]);
const one = doc.fork().reorder([5]); await one.save(); // split: a fork per page
const signed = await doc.saveIncremental({ sign: { field: { name: 'approval', page: 0, x: 40, y: 700, width: 180, height: 40 }, signer: nodeSigner({ key, certs }) } });
loadPdf(bytes, { password, budget, timeoutMs, signal }) reads lazily: the cross-reference (classic tables, xref
streams, hybrid files, incremental updates — the latest wins — object streams), the trailer, /Encrypt, /ID and
the page tree; an object is parsed when asked for, a stream decoded when needed (Flate, LZW, ASCII85, ASCIIHex,
RunLength, PNG and TIFF predictors; DCT, JPX, JBIG2 and CCITT are passed through undecoded). A broken
cross-reference is rebuilt by scanning for n g obj (doc.recovered), a wrong /Length found again from the next
endstream (doc.warnings says what was repaired). Encrypted files: the user or the owner password; RC4 (40–128
bit), AES-128 and AES-256 are read (doc.encryption); only AES is ever written.doc.page(i): width, height, the five boxes ([x0, y0, x1, y1], PDF space), rotation, userUnit,
extractText(), annotations(), draw(fn, { fonts, images }), rotate(deg), removeAnnotations().extractText() maps each code to Unicode through the font's ToUnicode CMap, else its encoding (WinAnsi, MacRoman,
Standard, /Differences glyph names), places it with the text and graphics matrices (form XObjects included) and
groups lines (a new line when the baseline moves by half the size; a space at a gap of a quarter of it, or a wide
TJ adjustment). It is not layout-perfect: no columns, no reading order beyond the stream's, no RTL reordering.doc.fields: full names, types (text, checkbox, radio, pushbutton, combo, list, signature), values, options and
widgets. A check box's value is true or false (what fill takes); its on-state export name (often Yes) is
onValue. doc.attachments: rawName, name (checked by the same file-name rules as the writer; null and
refused when it would spoof or is executable), mimeType, bytes(). doc.signatures: each signed field with its
/ByteRange, coversWholeFile, revision, bytesAfter and the CMS (not verified: signedBytes() gives the bytes
to verify it against).save() or saveIncremental(). copyPages(src, indexes, { at }), merge(docs),
removePages, reorder, movePage, rotate, draw, fill(values, { font }), flatten(), setInfo,
setXmp, removeAnnotations; fork() copies the plan (the source is shared).save(options) writes a NEW file through the writer (saveTo(sink, options) streams it): pages are deep-copied
as they are written (fonts, images, XObjects, annotations), equal objects written once (also across merged files),
destinations and links remapped to the new pages (a link to a page not copied is dropped), unused objects left out,
uncompressed streams compressed, object streams on. Drawn content (page.draw, flattened fields) is a form XObject
after the page's own content, which is wrapped in q … Q (closing any q it leaves open), so nothing the old
content does to the graphics state reaches it. The first document gives the catalog (form with every contributing
document's fields, outline of each, embedded files merged, structure tree when every page is its own, layers, viewer
preferences). PDF/A is kept when every document declares the same level and output intent (its profile, XMP and
identification kept; overlays obey the writer's PDF/A rules); otherwise dropped with a warning. A rewrite invalidates
signatures, so their values are dropped (reported in stripped). Options: compress, keepActiveContent,
encrypt, pdfa: 'keep' | false, keepStructure, creationDate, signal, timeoutMs.fill: text and combo values are strings, check boxes booleans, radio groups an export value, list boxes a string
or strings. Text and choice appearances are made again by the writer's form code at the widget's size and look
(/DA font, size and colour, /Q, /MK border and background, multiline, comb): with the /DA standard font, or
font (bytes; required in PDF/A and for text outside WinAnsi). A character the font lacks throws, naming the field.saveIncremental({ sign, keepActiveContent }) appends only the changed objects, a new cross-reference section
(the file's kind) with /Prev, so EXISTING SIGNATURES STAY VALID (poppler then reports the first one as "not total
document signed" while its own bytes still verify). It can fill fields, change the info, the XMP and rotation, and
sign: an empty signature field by name, or a new one ({ name, page, x, y, width, height }; no size: invisible), with
group F's signers, the /ByteRange over the whole file including the original bytes. An encrypted file's new objects
use its own AES key; RC4 files cannot be updated (writing RC4 is refused).mergePdfs(docs, options): every page of each, into a new file. A merged PDF/UA (or PDF/A-a) file is no longer
tagged: the structure tree is kept only when every page comes from one document (and the form is not flattened),
so a merge drops it with /MarkInfo and /Lang, the XMP's PDF/UA identification (pdfuaid) goes too, PDF/A-a is
claimed as PDF/A-b, and warnings says "the structure tree (tags) was dropped … the result is not tagged (no
longer PDF/UA …)". Tag the merged content again with the writer if the result must be PDF/UA.PdfReadError with a code: E_MALFORMED, E_BUDGET, E_DEPTH, E_CYCLE,
E_TIMEOUT, E_ABORTED, E_PASSWORD, E_UNSUPPORTED, E_ACTIVE.In short:
/AA, no form scripts; URLs are limited to http, https and mailto (widen per link with
allowSchemes, never to javascript:, data:, file: or vbscript:). Every caller string is written escaped.save() and mergePdfs() drop JavaScript, launch and submit actions, /AA,
XFA, RichMedia and every annotation or action outside an allowlist, and report it in stripped
(keepActiveContent: true opts out). saveIncremental() cannot strip (the old bytes stay), so it scans the whole
file and refuses (E_ACTIVE) instead.budget, timeoutMs, signal); exceeding one is a PdfReadError (E_BUDGET, E_TIMEOUT…), never
a hang or an out-of-memory crash. Images, attachments and Factur-X XML have their own size caps.The details, and what the library refuses and why:
| Refused | Why |
|---|---|
| RC4 encryption (40- and 128-bit, V1–V3 / R2–R3) | broken: a biased key stream and brute-forceable 40-bit keys; it only looks like protection |
| Encryption in PDF/A | ISO 19005 forbids it: an archive must open anywhere, forever |
| Turning off the accessibility permission in PDF/UA | ISO 14289 needs assistive technology to read the content (forced on, with a warning) |
| An empty owner password | it would give everyone full access; leave it out for a random one |
| Passwords over 1024 characters; control, bidi, private-use or unassigned characters (AES-256); non-Latin-1 (AES-128) | bounded input, and SASLprep, so every reader derives the same key |
A signer's CMS that is not one DER SignedData, is larger than reserve, or (with timestamp) carries no token | garbage must not land in /Contents; a dropped timestamp would downgrade B-T to B-B silently |
| A second signature in one document as it is created | it needs an incremental update: saveIncremental({ sign }) |
| A Factur-X XML with a DOCTYPE, ENTITY or other markup declaration, over 10 MB, or not UTF-8 | the XML is data: nothing may expand (billion laughs, external entities); it is never given to an XML parser |
| Caller text inserted into XMP unescaped | title, author, subject and keywords are escaped (& < > " '; characters XML cannot carry dropped); schema prefixes and names are checked as XML names |
An attachment over maxBytes, or with a spoofed name | the size is checked before any copy; names go through the same checker as page.attachFile |
Crypto comes from the platform only (WebCrypto, node:crypto in Node); no AES or SHA is hand-written. The key derivations of the standard security handler (ISO 32000-2 Algorithm 2.B; ISO 32000-1 Algorithms 2, 3, 5) are written here, as the spec composes them, and checked against vectors from qpdf. Passwords and keys never appear in an error. JavaScript, launch and submit actions cannot be written at all (see Forms and Links).
Reading files from strangers. The reader treats every byte as hostile:
| Bound | Default (budget option) |
|---|---|
| Decoded stream bytes, the whole document / one stream (every filter and predictor counts as it produces, so a zip bomb stops at the cap: a 302-byte stream that inflates to 10 GB stops at 128 MB) | maxDecoded 512 MB / maxStream 128 MB |
| Parsing steps (tokens, xref rows, tree nodes, operators); time | maxSteps 200 M; timeoutMs, signal |
| Cross-reference entries and scanned objects held; one page's text pieces | maxObjects 5 M; maxTextItems 1 M (and 16 M characters a page, ActualText included) |
| Nesting of arrays and dictionaries (an explicit stack, never recursion) | 256 |
| A chain of indirect references | 32 |
Every count and length is bounded by the bytes actually there (xref rows, /N, /Length, strings, /Count is never
trusted); loops are cut where they can occur (/Prev, page tree /Kids, outline /Next, AcroForm /Kids, an object
stream inside an object stream, form XObjects drawing themselves); recovery is one bounded pass.
Active content is never carried over unless keepActiveContent: true. One registry (src/reader/policy.js) says
what is allowed, and both save paths use it:
| Kept | Dropped (and reported in stripped) |
|---|---|
| Actions: GoTo, URI (plain-ASCII bytes accepted by the writer's URL check — http, https, mailto, ftp — and written as normalised), Named page moves, ResetForm | every other action (JavaScript, Launch, SubmitForm, ImportData, GoToR, GoToE, Hide, Movie, Sound, Rendition, RichMediaExecute, SetOCGState, Trans, GoTo3DView, Thread, unknown), wherever it is: /A, /OpenAction, /Next arrays, /PA, through references, or any dictionary whose /S is an action type |
| Annotations: Link, Text, FreeText, Line, Square, Circle, Polygon, PolyLine, Highlight, Underline, Squiggly, StrikeOut, Stamp, Caret, Ink, Popup, FileAttachment, Widget | RichMedia, Screen, Movie, Sound, 3D and anything else; every /Annots element and form widget is checked by position |
File specifications whose every name key passes the writer's file-name check and agrees in extension (written back as the checked /UF and /F, with one embedded stream) | any other (/F "evil.exe" behind a clean /UF, /DOS, a spoofed double extension) |
| — | /AA, /JS, /Names /JavaScript, the AcroForm's /XFA |
An attachment that is itself a PDF is copied as data: its own content is not sanitised (opening it is a separate act).
An incremental update cannot strip anything: the original bytes stay, and a reader that rebuilds the
cross-reference, shows an earlier revision or follows /Prev finds them again. So saveIncremental checks the WHOLE
file first — every object in the bytes (the parser's own lexer plus a byte scan, every duplicate, every object stream,
every cross-reference entry) against the same registry — and refuses (E_ACTIVE, naming what it found) if there is
any active content, or if anything cannot be read (fail closed), unless keepActiveContent: true. For files from
strangers, save() is the safe path (it rewrites the file without the active content; this invalidates existing
signatures).
This is why saveIncremental is slower by design. Appending a few objects could be done without reading the
original, but then active content hidden in it (a shadow attack: an earlier revision, an unreferenced object, a
duplicate, an object stream the latest cross-reference does not point at) would ride along under your new signature.
So it reads and scans the whole file first, every time: a large file costs a full parse before a byte is appended.
Safer, slower, on purpose.
Signed documents (signature policy). saveIncremental reads every signature's permissions and takes the
strictest: DocMDP from the catalog /Perms and from each signature's /Reference in every revision (no /P means
P=2), FieldMDP from each /Reference and each signed field's /Lock, and ReadOnly from any ancestor field. Anything it
cannot read or does not know refuses the update (E_SIGNED, fail closed).
| The document | Allowed | Refused |
|---|---|---|
| certified P=1 | nothing | every update, including a new signature |
| certified P=2 or P=3 | fills (opt-in, below) and new signatures | rotation, Info/XMP changes |
| signed, no DocMDP | fills (opt-in) and new signatures | rotation, Info/XMP changes unless allowChangesAfterSigning: true |
| a locked (FieldMDP) or ReadOnly field | — | filling it |
Filling a form after it was signed needs allowFillAfterSigning: true. Viewers show such a document as "changed
after signing", and refilling widgets that existed before signing is how "shadow attacks" (Mainka et al., USENIX
Security 2021) make a signed document look different while its signature still verifies. As a second guard the filled
widgets may cover at most 40% of a page in all, and a widget with an opaque background may not lie over the page's text.
textMapping: 'actualText', readers that ignore ActualText
or close it early (pdf.js; a tester saw an older MuPDF drop a line's last Bengali cluster) lose the spanned
clusters: the writer closes every span after its cluster's last glyph, and MuPDF 1.28.2 (PyMuPDF) reads Bengali,
Devanagari and the other test scripts whole.pdf.attach); a Factur-X invoice's
content is not validated.save()).See NOTES.md for the plan, and ARCHITECTURE.md for extending the library.
From 1.0.0 this package follows semantic versioning.
What 1.0 promises (the public API):
@reportwright/pdf (index.d.ts), @reportwright/pdf/write (the writer without the reader,
write.d.ts) and @reportwright/pdf/fflate (fflate as bundled here, fflate.d.ts), and ./examples/* as files.createPdf, toBytes, Page, loadPdf, mergePdfs, bulk, BULK_TASKS, nodeSigner, cmsSigner, readFont,
checkSubset, svgPathOps, cmyk, STANDARD_NAMES, PdfReadError (and its code values), pdf.core
(PdfCore, the low-level extension API) and the option and result types.PdfReadError codes.Not public: __bulkWorker (@internal: the bulk worker's entry, exported only so the worker can load it from the
same bundle), anything reached through dist/ or src/ by path, and the text-position internals of the reader.
Rules: breaking changes only in a major release, listed under Changes with their replacement and
deprecated (typed @deprecated, noted here) for at least one minor release first. Security fixes may change
behaviour in a patch release when that is what closes the hole (for example a tighter read budget); the change note
says so.
Releases are published to npm by GitHub Actions from a GitHub Release (tag v<version>). The one-time NPM_TOKEN
setup and the steps are in RELEASING.md.
1.0.0: the first stable release; the API is the one in Public API and stability. No
behaviour change from 0.1.0-beta.15. __bulkWorker is marked @internal (it was already documented as internal).
Upgrading from the betas: install without a tag (npm i @reportwright/pdf, latest is 1.0.0; next was the beta
line) and pin ^1.0.0. From before beta.14: a check box's doc.fields value is true/false, its on-state name is
onValue. From before beta.13: built-in TrueType subsets renumber glyphs (a subsetter function and core keep glyph
IDs). From before beta.11: SignatureOptions page, width and height are optional and @reportwright/pdf/write
exists. Nothing exported by beta.15 was removed.
0.1.0-beta.15 (performance; no output change except the xref stream's compressed bytes): the xref stream is compressed
by Node's zlib (CompressionStream or fflate elsewhere) instead of always loading fflate, so a cold one-page PDF takes
26.3 ms instead of 32.7 ms (laptop, whole process from import); with objectStreamLevel unset the file is now the same
as at level 6. Unkerned left-to-right text with an embedded font is encoded through a per-font table (charCodeAt, no
string-keyed Map per character), the same bytes: 500-line pages 0.25 → 0.18 ms a page (−27%).
0.1.0-beta.14: doc.fields reads a check box's value as true/false (was its state name, 'Yes'/'Off'),
with the on-state name as onValue; Page and the internal __bulkWorker are declared in index.d.ts;
examples/invoice-facturx.mjs embeds a complete EN 16931 invoice (line items, VAT breakdown, payment terms) that CI
checks against the Factur-X XSD; the README notes pypdf's and MuPDF's Indic extraction quirks.
0.1.0-beta.13: the built-in TrueType subset renumbers its glyphs and drops the tables a PDF does not read (name,
OS/2, gasp; OpenType/CFF also drops name and OS/2): a 19-character DejaVu Sans line is 6.5 KB, was 20.2 KB.
Renders and extracted text are unchanged. A subsetter function, and core, still keep glyph IDs.
0.1.0-beta.13: the README's benchmarks (wins and losses) were published with the package; they were beta.12's GitHub run. They are superseded by the QA run in Benchmarks.
0.1.0-beta.12: the build no longer keeps function names. esbuild's keepNames wrapped every closure in an Object.defineProperty call, which made writing about 35% slower (10,000 lines 182 → 117 ms). PdfReadError sets its own name; stacks map through the sourcemap.
0.1.0-beta.11: pdf.core, the low-level API under createPdf, is documented (PdfCore in the types), with
core.imageResource; encryption now covers every literal and hex string in direct objects (it leaked some and threw
on others); readFont and checkSubset read a font's metrics and check a subset before embedding; form fields take
a caller's appearance, da, structParent and widgetRef; a document whose pages were written through core can
be signed (an invisible field), with a PKCS#12 example (examples/p12-signer.mjs); svgPathOps turns SVG path data
into path operators; the build is minified, and @reportwright/pdf/write exports the writer without the reader; the
page, width and height of SignatureOptions are optional.
It includes everything from beta.9 and beta.10.
0.1.0-beta.10: a WritableStream's writer lock is released when the export ends, fails or is stopped (timeoutMs,
signal), so the caller can reuse or cancel the stream; the abort reason is still the original error.
0.1.0-beta.9: stamping every page (page.draw then save()) is about 35% faster on a 1,000-page file: a page's open
graphics states are counted with a byte scan instead of a full parse, and FlateDecode inflates whole, valid zlib
streams with Node's zlib (damaged, truncated, raw or over-budget streams still go through fflate as before); the output
is byte-identical. bulk starts an item's itemTimeoutMs clock when its worker is ready, so a respawned worker's
start-up no longer fails good files; a stopped export (timeoutMs or signal) aborts its WritableStream even when
the stop lands between two calls.
0.1.0-beta.2: a left-to-right shaped cluster in an ActualText span has its text only in the ActualText, so MuPDF
no longer reads it twice (pdf.js, which ignores ActualText, now misses those clusters; poppler, PDFium and
extractText read them); extractText drops WJ (U+2060) and reads a code a ToUnicode skips as nothing (U+FFFD
only when the font has no mapping at all); @reportwright/pdf/examples/* can be imported.
0.1.0-beta.1: shaped text (Indic, Arabic) extracts once and in order in pdf.js, poppler and extractText;
extractText honours ActualText, reads unmapped glyphs as U+FFFD, falls back to an embedded TrueType cmap, spaces
separate text objects (spreadsheet cells), orders a line along its baseline (rotated text too), and stops a
2 M-operator page at 170 MB (maxTextItems 1 M); standard-font text writes 40% faster; variable fonts warn; the
package ships examples/. The list with details: NOTES.md ("Changes") in the repository.
FAQs
A streaming PDF writer for Node and browsers with no runtime dependencies: flat memory, PDF/A-1b to 3a, PDF/UA-1, Factur-X, embedded TrueType with Unicode text.
The npm package @reportwright/pdf receives a total of 2,725 weekly downloads. As such, @reportwright/pdf popularity was classified as popular.
We found that @reportwright/pdf demonstrated a healthy version release cadence and project activity because the last version was released less than a year ago. It has 1 open source maintainer collaborating on the project.
Security News
Cloudflare is acquiring Deno’s team, which will provide another year of bug fixes and security updates before ending support for the runtime.

Security News
Anthropic’s free OSS Scanner uses Mythos and other Claude models to find open source vulnerabilities and send maintainers reports with proposed fixes.

Security News
On Front Lines’ Early Adopters: CISO podcast, Andrew Becherer shares lessons from Datadog, weighs the long-term costs of AI-built tools, and explains how founders can actually gain a CISO’s trust.