@samuraizer/cli
Local-first CLI that turns meeting recordings into transcripts, summaries, action items, and decisions — entirely on your machine. No cloud, no subscriptions, no data leaving your network.
Reference implementation of the memnex specification. All outputs conform to memnex v0.2, including a full provenance chain.
💻 System Requirements
| 8 GB | qwen2.5:3b |
| 16 GB | qwen2.5:7b |
| 32 GB+ | qwen2.5:14b (default) |
Apple Silicon (M1/M2/M3/M4) and recent x86 CPUs with AVX2 are recommended.
Whisper transcription is CPU/Metal-accelerated; LLM inference uses Ollama's defaults.
⚙️ Prerequisites
Install the required tools:
Start Ollama and pull a model:
ollama serve
ollama pull qwen2.5:14b
📦 Installation
npm install -g @samuraizer/cli
Migrating from the legacy samuraizer package? Versions ≤ 0.2.0 of the unscoped samuraizer package on npm are deprecated. Run npm uninstall -g samuraizer && npm install -g @samuraizer/cli to migrate. The CLI binary on your PATH is still called samuraizer.
🚀 Quick Start
samuraizer init
samuraizer process meeting.m4a
On a 30-minute recording this typically takes 3–5 minutes on Apple Silicon and 8–15 minutes on x86 CPUs, depending on the model.
🧪 Commands
Process an audio file
samuraizer process meeting.m4a
samuraizer process meeting.m4a --verbose
samuraizer process meeting.m4a --force
samuraizer process meeting.m4a --verbose --force
Run individual steps
samuraizer normalize input.m4a output.wav
samuraizer summarize transcript.txt
samuraizer actions transcript.txt
samuraizer decisions transcript.txt
Configuration
samuraizer init
samuraizer config path
samuraizer config get
Other
samuraizer --help
samuraizer --version
⚙️ Configuration
Samuraizer uses a global JSON config file.
Config location
- macOS:
~/Library/Application Support/samuraizer/config.json
- Linux:
~/.config/samuraizer/config.json
- Windows:
%AppData%/samuraizer/config.json
Example config
{
  "model": "qwen3.5:14b",
  "ollamaBaseUrl": "http://127.0.0.1:11434",
  "whisperCommand": "whisper-cli",
  "whisperModelPath": "/absolute/path/to/ggml-model.bin",
  "language": "en",
  "ffmpegCommand": "ffmpeg",
  "ffprobeCommand": "ffprobe"
}
Config fields
- model — LLM model used for analysis (summary, action items, decisions)
- ollamaBaseUrl — URL where Ollama is running
- whisperCommand — Command used to run Whisper
- whisperDevice (optional) — GPU/device whisper-cli runs on. Accepts a device index (
0, 1), a comma-separated list ("0,1"), or a GPU UUID; value semantics match CUDA_VISIBLE_DEVICES. Omit to use the default device.
- ffmpegCommand — Command used for audio processing
- ffprobeCommand — Command used for audio inspection
Every config field can also be overridden with an environment variable, e.g. SAMURAIZER_WHISPER_DEVICE=1 samuraizer process meeting.m4a.
Selecting a GPU
If your machine has multiple GPUs, pin whisper transcription to a specific one:
{
  "whisperDevice": 1
}
Or per-run, without editing the config:
SAMURAIZER_WHISPER_DEVICE=1 samuraizer process meeting.m4a
📂 Example output
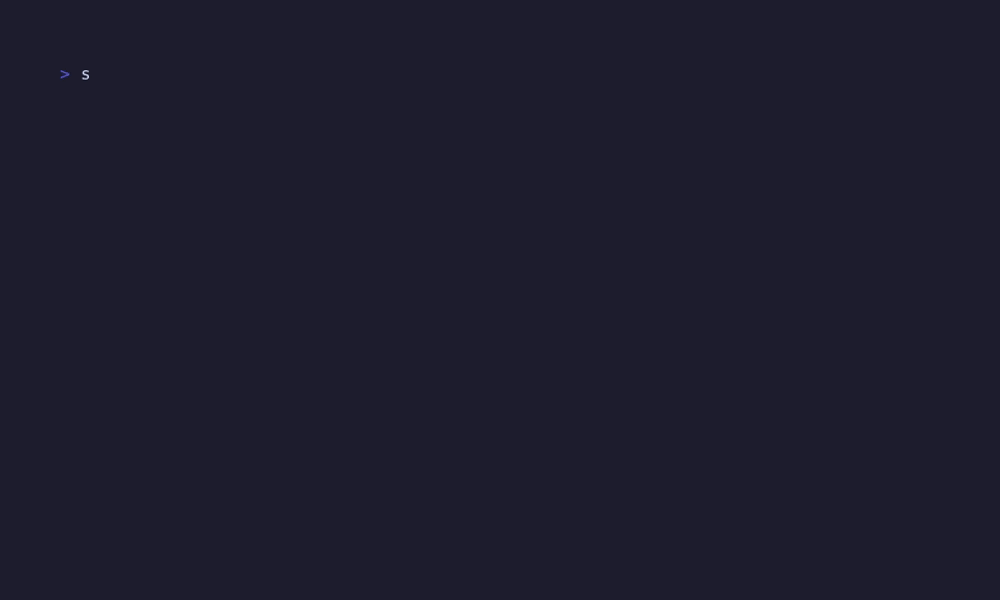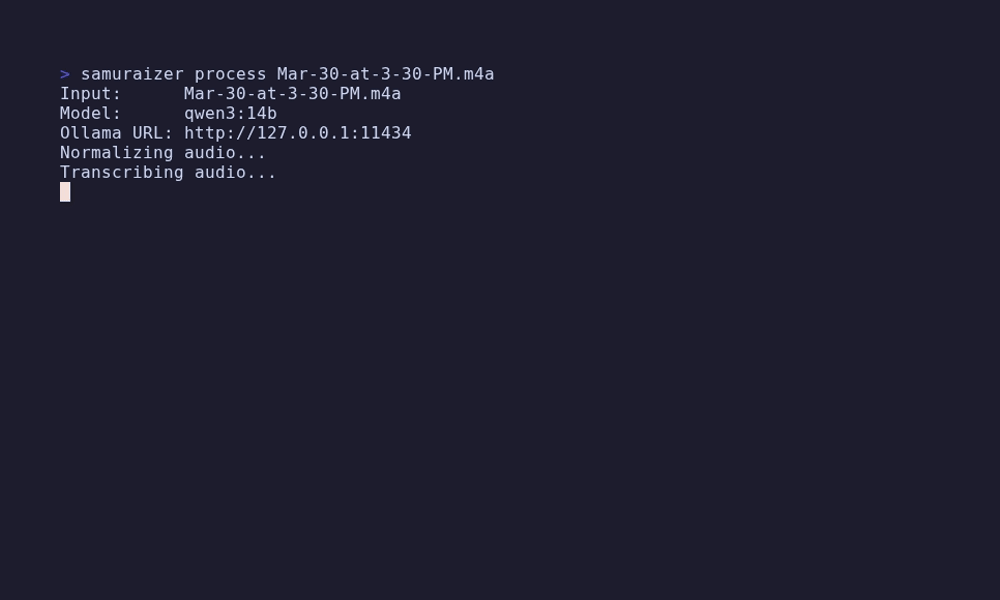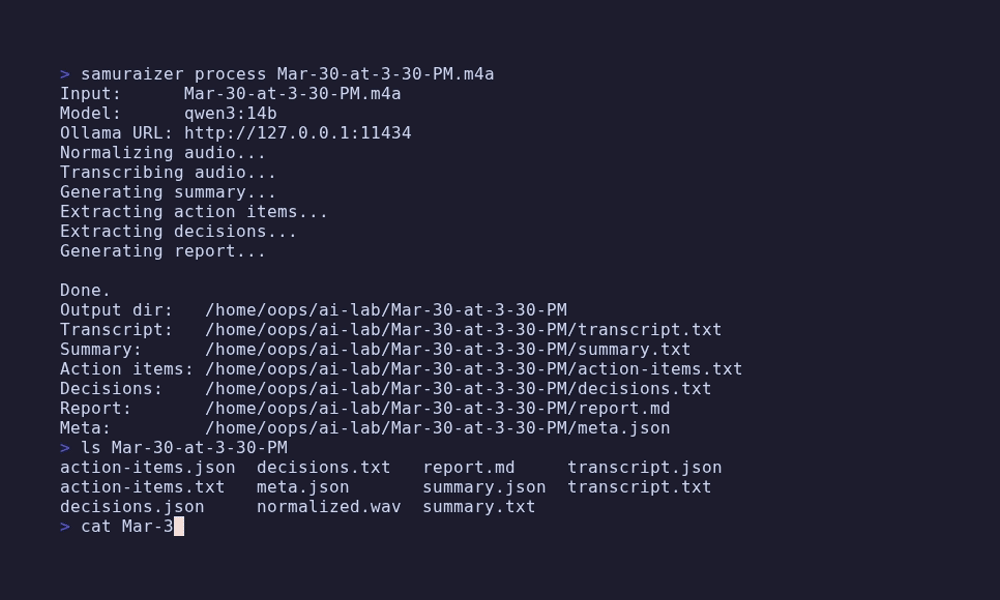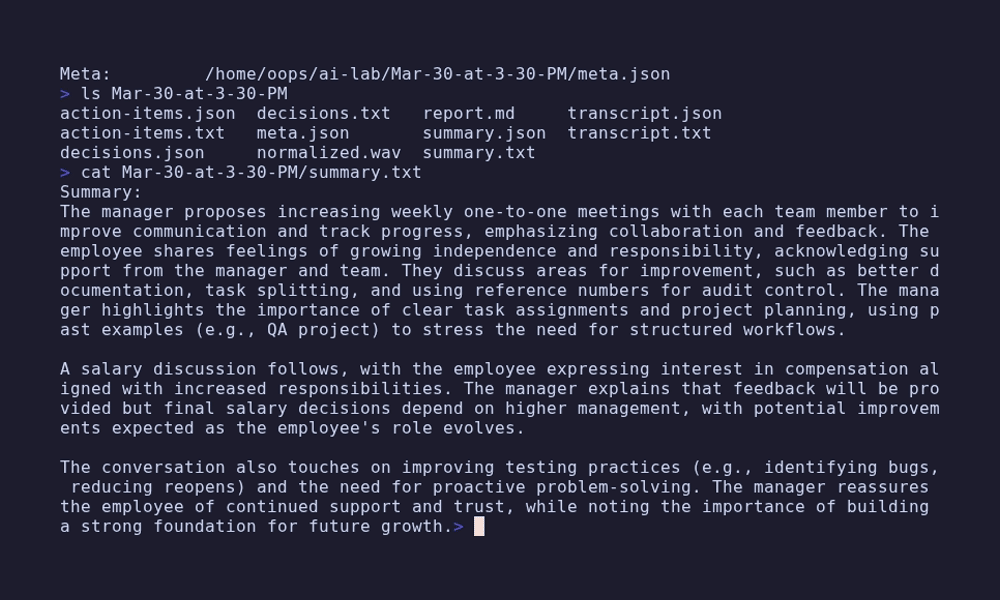
After processing, you'll find structured files in output/<recording-name>/:
output/meeting/
  transcript.txt
  summary.txt
  action-items.json
  decisions.json
  report.txt
  meeting.json
The meeting.json file is a memnex v0.2-conforming document combining all outputs with a full provenance chain.
summary.txt
Team standup focused on Q2 roadmap and infrastructure migration.
The frontend team will start the Next.js upgrade next week...
action-items.json
[
  {
    "owner": "Alice",
    "task": "Set up staging environment for migration testing",
    "deadline": "by end of week"
  },
  {
    "owner": "Bob",
    "task": "Review the auth refactor PR",
    "deadline": null
  }
]
decisions.json
[
  {
    "decision": "Adopt Next.js 15 for the new dashboard",
    "rationale": "Better SSR and built-in App Router support"
  }
]
🔁 Resume behavior
Samuraizer skips steps whose output files already exist. If processing crashes or you stop it mid-pipeline, just re-run the same command — completed steps are reused.
Use --force to recompute everything from scratch.
⚠️ Troubleshooting
Ollama not running
ollama serve
Ollama on a non-default port
Update ollamaBaseUrl in your config:
{
  "ollamaBaseUrl": "http://127.0.0.1:11500"
}
Out of memory during analysis
Switch to a smaller model:
ollama pull qwen3.5:14b
Then update model in your config to qwen2.5:7b (or qwen2.5:3b on machines with 8 GB RAM).
Model not found
Make sure the model in your config is actually pulled:
ollama list
ollama pull <model-name>
whisper-cli not in PATH
Build whisper.cpp and ensure the binary is on your PATH, or set the absolute path in whisperCommand in your config.
ffmpeg not found
macOS:
brew install ffmpeg
Linux:
sudo apt install ffmpeg
sudo pacman -S ffmpeg
sudo dnf install ffmpeg
Windows:
winget install Gyan.FFmpeg
🤖 AI agent access (MCP)
Samuraizer also ships with a companion MCP server, @samuraizer/mcp-server, that lets AI agents (Claude Desktop, Claude Code, MCP Inspector) query your processed meetings and run the pipeline on demand.
📝 Changelog
See CHANGELOG.md for release history.
📄 License
MIT — see LICENSE.
🔗 Source code
Part of the Samuraizer monorepo: github.com/UladzKha/samuraizer-cli.



