


Company News
Jerod Santo Joins Socket as Head of Media
Allow myself to introduce... myself.
By Jerod Santo - Sep 14, 2026
markdown-for-agents
Advanced tools
Runtime-agnostic HTML to Markdown converter built for AI agents. One dependency, works everywhere.

Runtime-agnostic HTML to Markdown converter built for AI agents. One dependency, works everywhere.
Try it in the playground — paste a URL or HTML and see the conversion live.
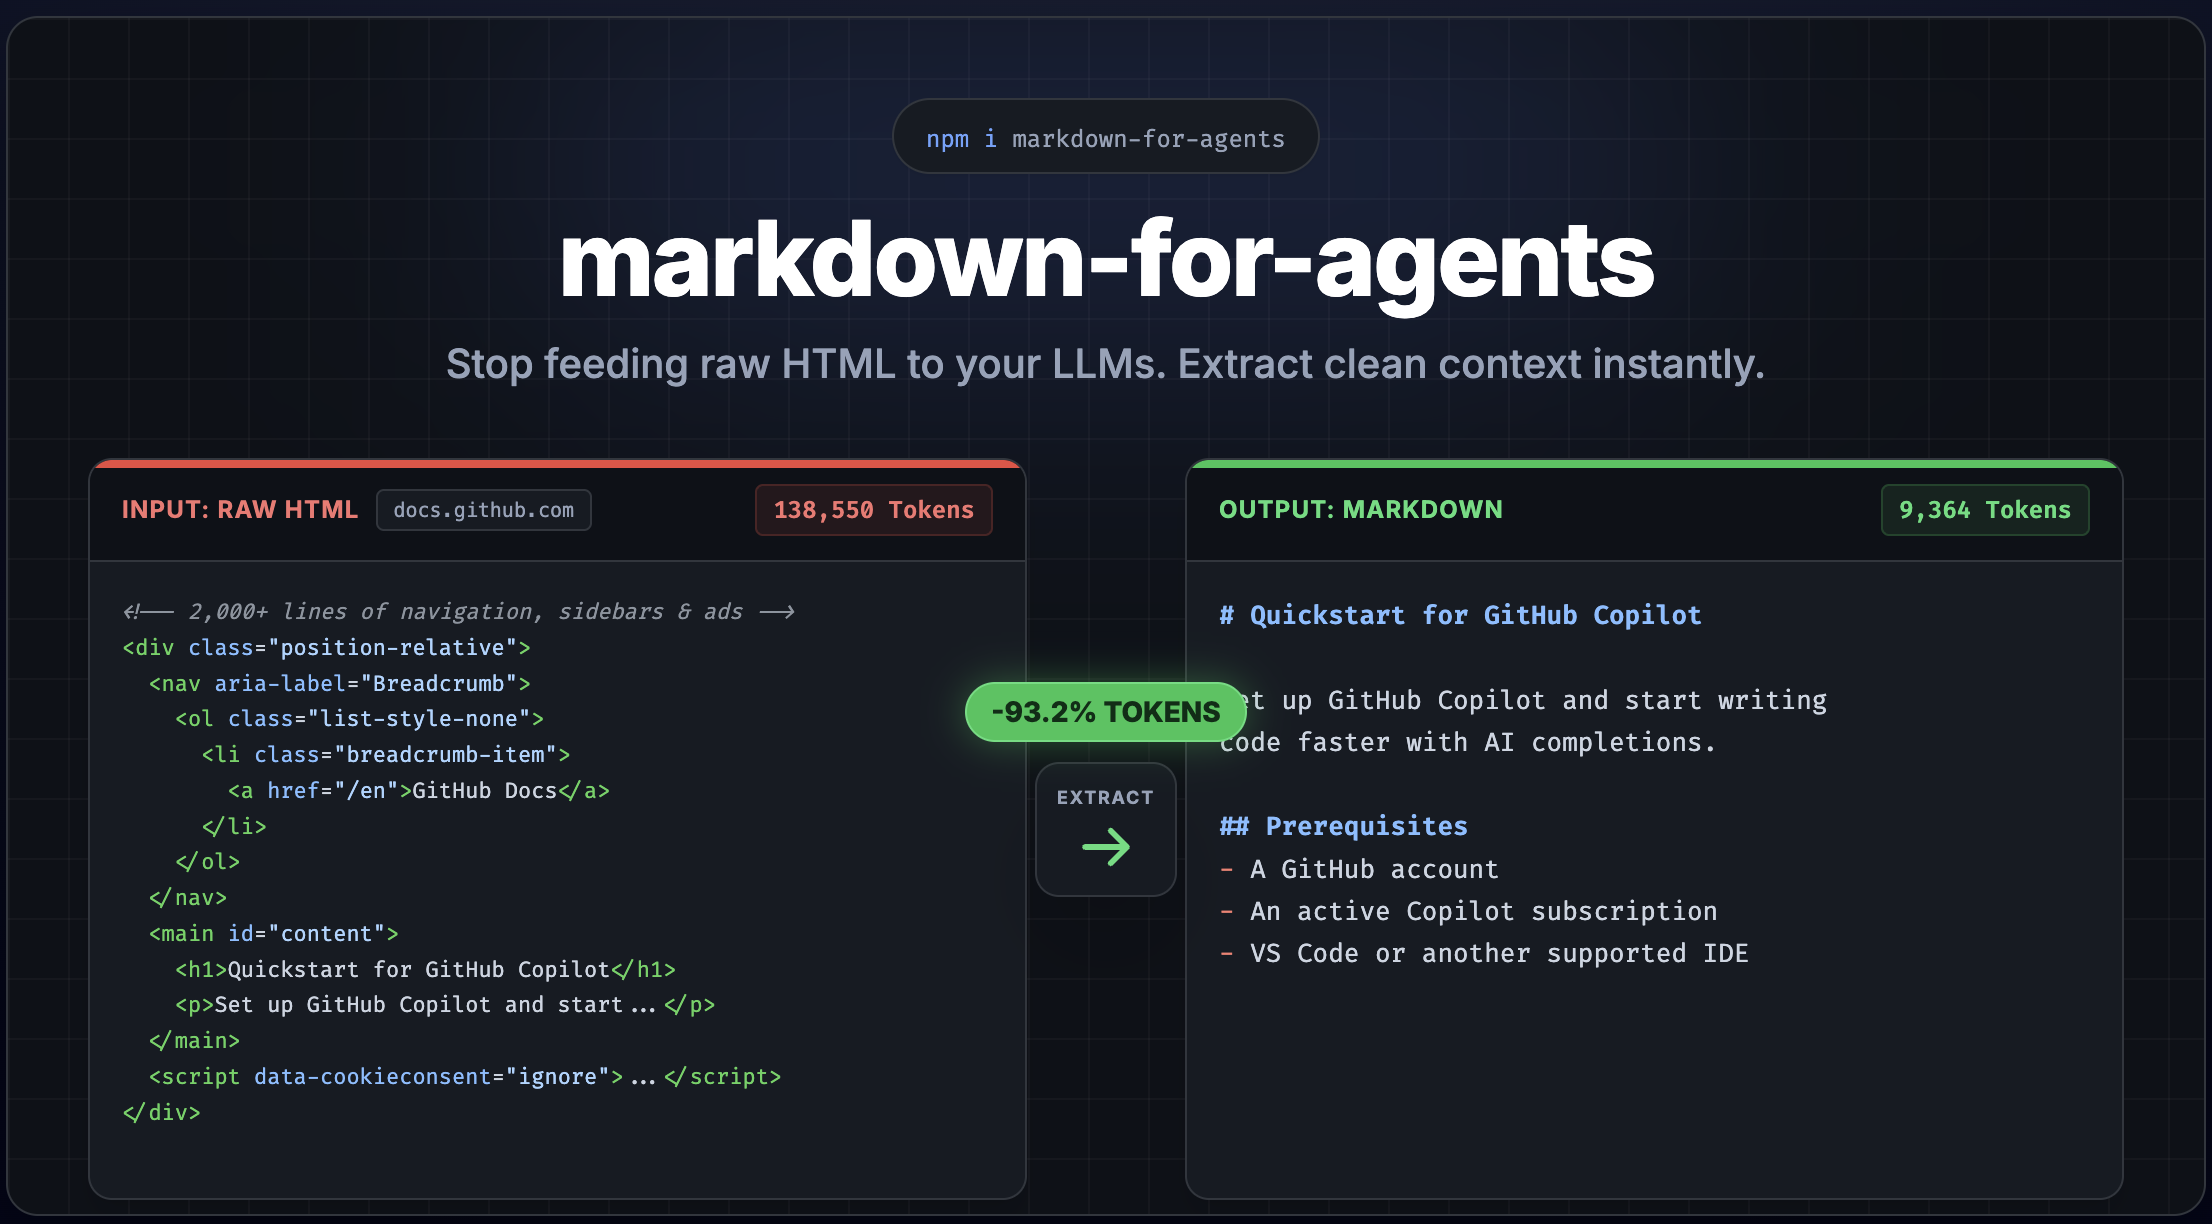
Audit any URL — no installation required:
npx @markdown-for-agents/audit https://docs.github.com/en/copilot/get-started/quickstart
           HTML            Markdown        Savings
───────────────────────────────────────────────────
Tokens     138,550         9,364           -93.2%
Chars      554,200         37,456          -93.2%
Words      27,123          4,044
Size       541.3 KB        36.6 KB         -93.2%
Convert any HTML page into clean, token-efficient Markdown — with built-in content extraction to strip away navigation, ads, and boilerplate. Inspired by Cloudflare's Markdown for Agents.
<head> and prepends YAML frontmattercontent-signal HTTP header for publisher consent (AI training, search, AI input)Accept: text/markdownnpm install markdown-for-agents
import { convert } from 'markdown-for-agents';

const html = `
  <h1>Hello World</h1>
  <p>This is a <strong>simple</strong> example.</p>
`;

const { markdown, tokenEstimate, contentHash } = convert(html);

console.log(markdown);
// # Hello World
//
// This is a **simple** example.

console.log(tokenEstimate);
// { tokens: 12, characters: 46, words: 8 }

console.log(contentHash);
// "d-1a3b4c5" — deterministic, use as ETag or cache key
Real-world HTML pages are full of navigation, ads, sidebars, and cookie banners. Enable extraction mode to get just the main content:
const { markdown } = convert(html, { extract: true });
This strips <nav>, <header>, <footer>, <aside>, <script>, <style>, ad-related elements, cookie banners, social widgets, and more.
By default, metadata is extracted from the HTML <head> element and prepended as YAML frontmatter. This aligns with Cloudflare's Markdown for Agents convention.
const html = `<html>
  <head>
    <title>My Page</title>
    <meta name="description" content="A great page about things">
    <meta property="og:image" content="https://example.com/hero.png">
  </head>
  <body><p>Content here</p></body>
</html>`;

const { markdown } = convert(html);
// ---
// title: My Page
// description: A great page about things
// image: https://example.com/hero.png
// ---
// Content here
Extracted fields: title (from <title>), description (from <meta name="description">), image (from <meta property="og:image">).
Disable it or merge custom fields:
// Disable frontmatter
convert(html, { frontmatter: false });

// Merge custom fields (custom overrides extracted)
convert(html, { frontmatter: { author: 'Jane', title: 'Custom Title' } });
Framework middleware is available as separate packages — they serve Markdown automatically when AI agents request it via Accept: text/markdown:
// Express
import { markdown } from '@markdown-for-agents/express';
app.use(markdown());

// Fastify
import { markdown } from '@markdown-for-agents/fastify';
fastify.register(markdown());

// Hono
import { markdown } from '@markdown-for-agents/hono';
app.use(markdown());

// Next.js (auto-unwraps /_next/image URLs)
import { withMarkdown } from '@markdown-for-agents/nextjs';
export default withMarkdown(handler);

// Any Web Standard server (Cloudflare Workers, Deno, Bun)
import { markdownMiddleware } from '@markdown-for-agents/web';
const mw = markdownMiddleware();
The middleware inspects the Accept header. Normal browser requests pass through untouched. When an AI agent sends Accept: text/markdown, the HTML response is automatically converted.
| Package | Framework |
|---|---|
@markdown-for-agents/express | Express |
@markdown-for-agents/fastify | Fastify |
@markdown-for-agents/hono | Hono |
@markdown-for-agents/nextjs | Next.js |
@markdown-for-agents/web | Web Standard (Cloudflare Workers, Deno, Bun) |
Override how any element is converted, or add support for custom elements:
import { convert, createRule } from 'markdown-for-agents';

const { markdown } = convert(html, {
    rules: [
        createRule(
            node => node.name === 'div' && node.attribs.class?.includes('callout'),
            ({ convertChildren, node }) => `\n\n> **Note:** ${convertChildren(node).trim()}\n\n`
        )
    ]
});
Custom rules have higher priority than defaults and are applied first.
All options are optional. Defaults are shown below:
convert(html, {
    // YAML frontmatter from <head> metadata
    frontmatter: true, // false | Record<string, string>

    // Content extraction
    extract: false, // true | ExtractOptions

    // Custom conversion rules
    rules: [], // Rule[]

    // Base URL for resolving relative links and images
    baseUrl: '', // "https://example.com"

    // Heading style
    headingStyle: 'atx', // "atx" (#) or "setext" (underline)

    // Bullet character for unordered lists
    bulletChar: '-', // "-", "*", or "+"

    // Code block style
    codeBlockStyle: 'fenced', // "fenced" or "indented"

    // Fence character
    fenceChar: '`', // "`" or "~"

    // Strong delimiter
    strongDelimiter: '**', // "**" or "__"

    // Emphasis delimiter
    emDelimiter: '*', // "*" or "_"

    // Link style
    linkStyle: 'inlined', // "inlined" or "referenced"

    // Remove duplicate content blocks
    deduplicate: false, // true | DeduplicateOptions

    // Custom token counter (replaces built-in heuristic)
    tokenCounter: undefined, // (text: string) => TokenEstimate

    // Performance timing (populates convertDuration in result)
    serverTiming: false // true to measure conversion duration
});
Enable serverTiming to measure conversion duration. The result includes convertDuration (in milliseconds), and middleware adapters use it to set a Server-Timing header:
const { markdown, convertDuration } = convert(html, { serverTiming: true });
console.log(`Conversion took ${convertDuration}ms`);
// Middleware sets: Server-Timing: mfa.convert;dur=4.7;desc="HTML to Markdown"
By default, token estimation uses a fast heuristic (~4 characters per token). You can replace it with an exact tokenizer:
import { convert } from 'markdown-for-agents';
import { encoding_for_model } from 'tiktoken';

const enc = encoding_for_model('gpt-4o');

const { markdown, tokenEstimate } = convert(html, {
    tokenCounter: text => ({
        tokens: enc.encode(text).length,
        characters: text.length,
        words: text.split(/\s+/).filter(Boolean).length
    })
});
The custom counter receives the final markdown string and must return a TokenEstimate object with tokens, characters, and words fields. It flows through to middleware as well — the x-markdown-tokens header will reflect your counter's value.
Pass deduplicate: true to use defaults, or pass a DeduplicateOptions object to customize behavior:
const { markdown } = convert(html, {
    deduplicate: { minLength: 5 } // catch short repeated phrases like "Read more"
});
The minLength option (default: 10) controls the minimum block length eligible for deduplication. Blocks shorter than this are always kept. Lower it to catch short repeated phrases, raise it for more conservative deduplication.
Middleware can set a content-signal HTTP header to communicate publisher consent for AI training, search indexing, and AI input. This is opt-in — the header is only set when explicitly configured:
app.use(
    markdown({
        contentSignal: {
            aiTrain: true, // ai-train=yes
            search: true, // search=yes
            aiInput: true // ai-input=yes
        }
    })
);
// Sets header: content-signal: ai-train=yes, search=yes, ai-input=yes
Only explicitly set fields are included. Set a field to false to signal denial (e.g. aiTrain: false → ai-train=no). Omit a field to exclude it from the header entirely.
| HTML | Markdown |
|---|---|
<h1>...<h6> | # Heading (atx) or underline (setext) |
<p> | Paragraph with blank lines |
<blockquote> | > Quoted text |
<pre><code> | Fenced code block with language |
<hr> | --- |
<br> | Trailing double-space line break |
<ul>, <ol>, <li> | Lists with nesting and indentation |
<table> | GFM pipe table with separator row |
<script>, <style>, <noscript>, <template> | Stripped |
| HTML | Markdown |
|---|---|
<strong>, <b> | **bold** |
<em>, <i> | *italic* |
<del>, <s>, <strike> | ~~strikethrough~~ |
<code> | `inline code` |
<a> | [text](url) with title and baseUrl support |
<img> |  with title and baseUrl support |
<sub> | ~subscript~ |
<sup> | ^superscript^ |
<abbr>, <mark> | Pass-through (text preserved) |
The core package provides fine-grained imports for tree-shaking:
import { convert } from 'markdown-for-agents';
import { extractContent } from 'markdown-for-agents/extract';
import { estimateTokens } from 'markdown-for-agents/tokens';
| Runtime | Version | Status |
|---|---|---|
| Node.js | >= 22 | Tested |
| Bun | >= 1.0 | Tested |
| Deno | >= 2.0 | Tested |
| Cloudflare Workers | - | Compatible |
| Vercel Edge | - | Compatible |
| Browsers | ES2022+ | Compatible |
The @markdown-for-agents/audit package lets you measure token savings when converting HTML to Markdown. Fetch any URL and see exactly how many bytes and tokens you save:
npx agent-markdown-audit https://example.com
┌─────────┬──────────┬────────┐
│         │ Bytes    │ Tokens │
├─────────┼──────────┼────────┤
│ HTML    │ 48,291   │ 12,073 │
│ Markdown│ 8,412    │ 2,103  │
│ Saved   │ 82.6%    │ 82.6%  │
└─────────┴──────────┴────────┘
MIT
FAQs
Runtime-agnostic HTML to Markdown converter built for AI agents. One dependency, works everywhere.
The npm package markdown-for-agents receives a total of 2,226 weekly downloads. As such, markdown-for-agents popularity was classified as popular.
We found that markdown-for-agents demonstrated a healthy version release cadence and project activity because the last version was released less than a year ago. It has 1 open source maintainer collaborating on the project.
Company News
Allow myself to introduce... myself.

Research
/Security News
A Twitch browser extension on Chrome and Firefox forwards users’ live OAuth session tokens through proxies controlled by a Russian bot service.

Security News
Anthropic found biased reasoning and recklessness drove Claude Mythos 5 to publish malware on PyPI and compromise a security vendor.