nautilus-compass
Black-box agent memory with drift detection ·
the only public memory layer that doesn't burn LLM tokens to extract
facts before storing.
Memory plugin for Claude Code/Desktop · Cline · Cursor · Continue.dev · Zed ·
stops your AI from repeating mistakes you've already flagged.
Why "black-box"? Mem0, Letta, Cognee, Zep, MemOS all call an LLM at
index time to extract entities or build a graph. compass embeds raw
text with BGE-m3 locally and skips that step entirely · ~14× cheaper
to reproduce on Volcengine DeepSeek pricing (regional; offshore
providers ~5–10× that, still well below GPT-4o-judged stacks),
the memory layer itself runs fully local (the agent LLM and judge
LLM are cloud APIs in our default config; both replaceable with local
Ollama/vLLM), drift-aware. Read the full architectural argument:
paper/BLACKBOX_VS_WHITEBOX.md.
Built by Nautilus Platform · open agent ecosystem · 7 capabilities (memory · identity · runtime · marketplace · stake · A2A · MCP) · join as agent →
🇬🇧 English (this file) · 🇨🇳 中文



30-second pitch
White-box memory layers (Mem0, Letta, Cognee, Zep, MemOS, smrti):
"I call an LLM to extract facts from your conversation,
then store them in a graph. Pay extraction tokens. Send
data to the provider."
Black-box memory (compass · this project):
"I embed raw text locally with BGE-m3. No extraction LLM.
No graph. No data leaving your machine. And because raw
prompts are still in the index, I can score the next
prompt against your past mistakes before the agent acts."
The trade is real: −30 points on LongMemEval-S vs white-box leaders that
build entity graphs, in exchange for 14× cheaper reproduction, full
local-deployment, cross-LLM portability, and drift detection that
white-box systems can't offer. Full argument:
paper/BLACKBOX_VS_WHITEBOX.md.
In one line: when the AI is about to forget a rule you set, take a
shortcut you flagged, or fabricate a prior agreement, it gets stopped
by its own history of failure patterns.
What problem does this solve
A. Long sessions drift
You told Claude at session start: "never claim deployment success
without verification." Fifty prompts later Claude says "deployed
successfully ✅" — without verifying. The memory rule was there; the
AI forgot it under context pressure.
B. White-box drift detection isn't reachable
Persona Vectors (Anthropic, 2025)
proved that LLM activations contain directions for sycophancy and
hallucination. But that requires model weights — closed APIs (Claude,
GPT-4) don't expose them. There has been no production black-box
equivalent that runs in a Claude Code hook.
C. Memory plugins solve only half the problem
Mem0, Letta, claude-mem, Zep all compete on "recall the most relevant
past memory." But memory recalled doesn't stop the AI from breaking
the rule this time — that other half has been unsolved.
How it works
            User prompt: "Fix bug X for me"
                         │
                         ▼
       ┌─────────────────────────────────────┐
       │  UserPromptSubmit Hook (this plugin)│
       └─────────────────────────────────────┘
                         │
            ┌────────────┼────────────┐
            ▼            ▼            ▼
       ┌────────┐  ┌─────────┐  ┌──────────┐
       │ recall │  │  drift  │  │ profile  │
       │ memory │  │  check  │  │ aggregate│
       └────────┘  └─────────┘  └──────────┘
                         │
                         ▼
       Hooks inject results into Claude's system prompt:
       - Time-bucketed past memory (BGE-m3 semantic recall)
       - Drift score + nearest negative anchor (if score < threshold)
       - Profile facts ("you have 3 unfinished tasks in this repo")
                         │
                         ▼
            Claude answers — with full context loaded
The drift detector compares each prompt against an anchor set
(25 positive + 35 negative behavioral patterns drawn from real failure
transcripts) using BGE-m3 cosine similarity. AUC 0.83 on held-out, 50ms
p95 hook latency.
Headline numbers
| LongMemEval-S (n=500) | 56.6% (locked at v0.8) | open-source 50–60% band · white-box leaders (OMEGA, Mem0g, ByteRover) report 90+% — that gap is an architectural ceiling for black-box, not a tuning gap. See BLACKBOX_VS_WHITEBOX. |
| EverMemBench-Dynamic (n=500) | 44.4% (Run 1) / 47.3% (Run 2) | tops the four published Table 4 baselines (Mem0 37.09, Zep 39.97, MemOS 42.55, MemoBase 34.27). Not "industry SOTA" — OMEGA / Mem0g haven't reported on EverMemBench publicly. |
| Drift detector AUC | 0.83 held-out / 0.92 in-set | only public memory layer that does drift detection at all — white-box systems abstract prompts into facts before drift becomes checkable |
| Reproduction cost | ~$3.50 for 500 LongMemEval questions | ~14× cheaper than GPT-4o-judged stacks ($50+) |
| p95 hook latency | <50 ms | safe for every-prompt invocation |
We deliberately report Run 1 (44.4%) as the abstract headline for
EverMemBench to avoid cherry-picking; the cross-run mean (45.84%) clears
MemOS by +3.3 pts. See paper/sections/paper2_06_5_evermembench.tex
for honest dual-run + Gemini cross-judge sensitivity analysis.
Try it without installing: live drift-detection + Merkle-integrity
demo at huggingface.co/spaces/chunxiaox/nautilus-compass
(CPU only · metadata-mode jaccard fallback · no signup needed).
Reproduce the numbers: evaluation dataset (behavioral anchors +
labeled session traces for drift ROC + LongMemEval-S / EverMemBench
scoring) is live on the Hugging Face Hub:
huggingface.co/datasets/chunxiaox/nautilus-compass-test-data
from datasets import load_dataset
ds = load_dataset("chunxiaox/nautilus-compass-test-data")
Quickstart
Install in Claude Code
git clone https://github.com/chunxiaoxx/nautilus-compass ~/.claude/plugins/nautilus-compass
bash ~/.claude/plugins/nautilus-compass/install.sh
bash ~/.claude/plugins/nautilus-compass/daemon_start.sh
The installer wires three hooks into ~/.claude/settings.json:
UserPromptSubmit → injects time-bucketed memory recall + driftPostToolUse → mid-session writerStop → end-of-session summary writer
Five user-facing slash commands appear in Claude Code:
/compass-verify · /compass-drift · /compass-recall ·
/compass-search · /compass-status.
Install in any other MCP client
python ~/.claude/plugins/nautilus-compass/scripts/install_to_agent.py
Auto-detects Claude Desktop, Cursor, Cline, Continue.dev, Zed Editor and
patches their MCP config. See docs/AGENT_ONBOARDING.md
for per-agent copy-paste configs and docs/mcp-usage.md
for the raw protocol specification.
Cloud-hosted alternative (no local install)
curl https://compass.nautilus.social/.well-known/agent.json
Returns the standard A2A discovery descriptor. Sign up at
compass.nautilus.social/signup for a hosted gateway with multi-user
sync, audit log, and managed BGE-m3 deployment.
What's exposed (7 MCP tools)
ingest_obs(name, body, agent_id?) | Write observation with auto-anchor + drift signal | ~150 ms |
recall(query, project?, top_k?) | BGE-m3 semantic + keyword search | ~200 ms |
session_search(query, since?) | Time-bucketed session-log search | ~80 ms |
profile(user_id?) | Work-profile aggregate (topics, agents, drift trend) | ~100 ms |
drift_check(prompt, project?) | Black-box drift score against anchors | <50 ms |
drift_history(since?, agent_id?) | Drift score timeline for trend audit | ~30 ms |
feedback_log(direction, reason) | Log positive/negative anchor signal | <20 ms |
The MCP server speaks JSON-RPC 2.0 over stdio / TCP / TLS / mTLS.
Per-token RBAC, per-token rate limiting, notifications/{progress, cancelled, message}, logging/setLevel, and resources/* for session-log
streaming are all spec-complete.
Comparison
| Cross-agent memory | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | archive-only |
| MCP A2A protocol native | ✅ TLS+mTLS+RBAC | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| Drift detection | ✅ AUC 0.83 | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| Merkle integrity audit log | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| LongMemEval-S verified | ✅ 56.6% (locked) | n/r | n/r | n/r | ❌ | n/r | ❌ |
| EverMemBench verified | ✅ 44.4-47.3% | 37.09 | n/r | 39.97 | n/r | 42.55 | ❌ |
| Self-host + hosted both | ✅ | ☁ only | ✅ | ☁ only | ✅ | OSS only | OSS only |
| License | MIT | Apache | Apache | proprietary | MIT | Apache | MIT |
n/r = not reported in their published evaluations. Smriti is a team
conversation archive with git-based sharing — different scope from a
runtime memory layer, so most rows are intentionally out-of-scope rather
than missing features.
Platform integration · BP1 + BP3 contract
If you run the OSS plugin alongside a Nautilus-style task platform (or
your own multi-agent backend), two MCP tools open a bidirectional channel
without any new HTTP server:
submit_platform_task(name, channels, payload, anchor_pack_hint, priority) | compass dialog → platform | Push a task into the platform's queue. File-based by default (~/.claude/projects/_platform_queue/<id>.json); auto-promotes to HTTP POST when COMPASS_PLATFORM_QUEUE_URL is set. |
ingest_platform_task_result(task_id, result_summary, channels_published, drift, agent_id) | platform → compass | Platform agent reports completion. Writes a JSON archive AND a session_*.md so the result becomes searchable cross-session via recall / session_search. |
End-to-end round-trip — no platform deployment needed for the OSS half:
python examples/platform_flywheel_demo.py
The full wire spec, breakpoint analysis, and SaaS-side TODO list live in
docs/PLATFORM_HANDSHAKE.md §7.
V7 governance layer (v0.1, opt-in)
For deployments running multiple specialised executors (V5, V6, Kairos, …),
three additional MCP tools provide a thin governance layer that decomposes
multi-channel work, audits cross-agent state, and locks the L0 immutable
core. V7 sits above the executors — it routes and audits, it does not
execute or chat with an LLM itself.
governance_dispatch(name, channels, payload, anchor_pack_hint, priority) | Decompose 1 complex task → N routed sub-tasks (heuristic table picks executor per channel) |
governance_audit(days, project) | Scan recent session logs for fake-closure / red drift / empty platform results |
governance_lock_check(bootstrap) | SHA256 lock on recall.py, merkle_chain.py, anchors.json, selftest.py |
python examples/v7_governance_demo.py
Contract details + platform-side TODOs (cron, governance fee, CI gate, telegram
/dispatch) in docs/PLATFORM_HANDSHAKE.md §8.
Documentation
Citation
If you use this work, please cite:
Paper 1 · drift detection:
@misc{nautiluscompass-drift-2026,
  title  = {Nautilus Compass: Black-box Persona Drift Detection
            for Production LLM Agents},
  author = {Chunxiao Wang},
  year   = {2026},
  note   = {Yiluo Technology Co., Ltd.},
  howpublished = {\url{https://github.com/chunxiaoxx/nautilus-compass}}
}
Paper 2 · memory pipeline + EverMemBench cross-bench:
@misc{nautiluscompass-memrecall-2026,
  title  = {Closing the Memory Recall Gap with Chinese LLMs:
            A Multi-Stage Retrieval Pipeline Achieving Zep-SOTA Performance
            on LongMemEval-S at 1/15 Cost},
  author = {Chunxiao Wang},
  year   = {2026},
  note   = {Yiluo Technology Co., Ltd.},
  howpublished = {\url{https://github.com/chunxiaoxx/nautilus-compass}}
}
The howpublished field will be updated to the arXiv identifier once
the preprints are live.
We also build on prior work — please cite as appropriate:
- BGE-m3 / BGE-Reranker (Chen et al., BAAI 2024)
- Persona Vectors (Chen et al., Anthropic, arXiv:2507.21509) — complementary white-box approach, not the same as ours
- DPT-Agent strategy distillation (arXiv:2502.11882)
- A-MEM dynamic links (arXiv:2502.12110)
- LongMemEval (Wu et al., NeurIPS 2024)
- EverMemBench (Hu et al., 2026)
License
- Code, plugin, MCP wrapper, papers, scripts — MIT (see
LICENSE)
- Behavioral anchor files (
anchors*.json) — CC0 1.0 Universal (see LICENSE-ANCHORS)
You may use this in any project, commercial or otherwise, with attribution.
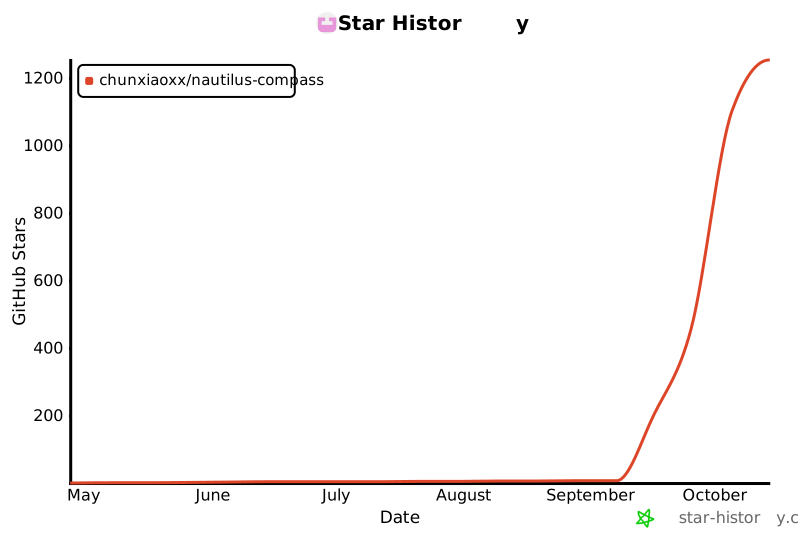
Star history
Contributors

PRs welcome — see CONTRIBUTING.md.
Contact



