


Security News
Happy Birthday, Shai-Hulud
It has been one year since Shai-Hulud made its first appearance on npm.
By Sarah Gooding - Sep 18, 2026
llm-preflight
Advanced tools
Last reviewed: 2026-09-08 · As of: v2.12.0


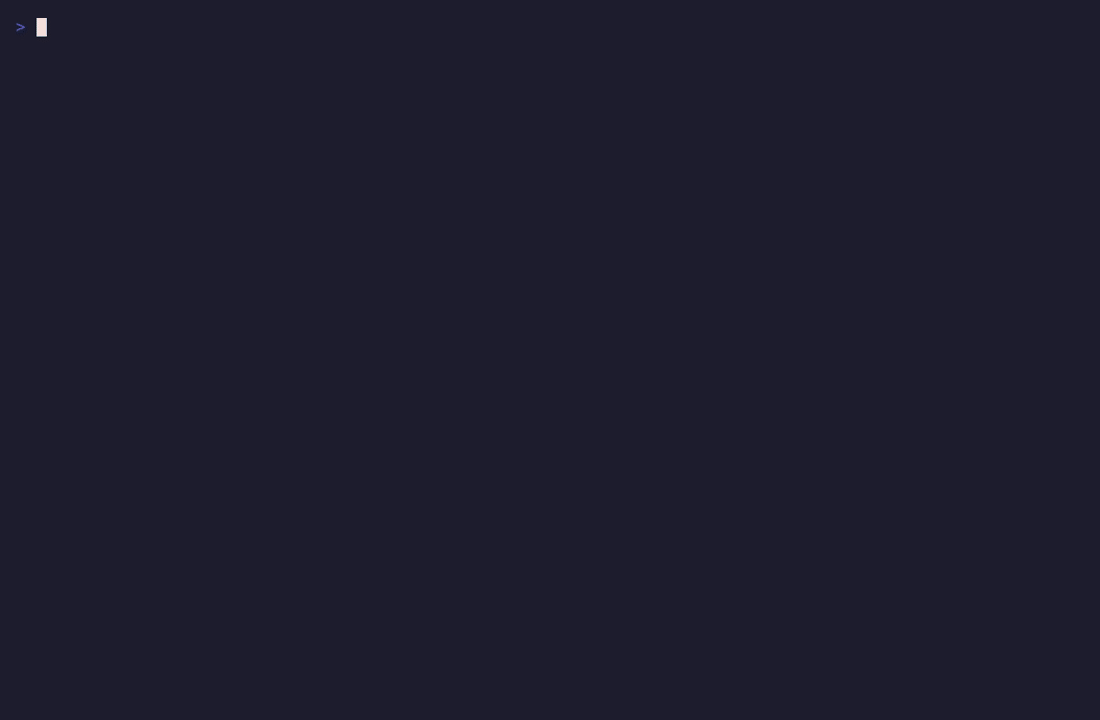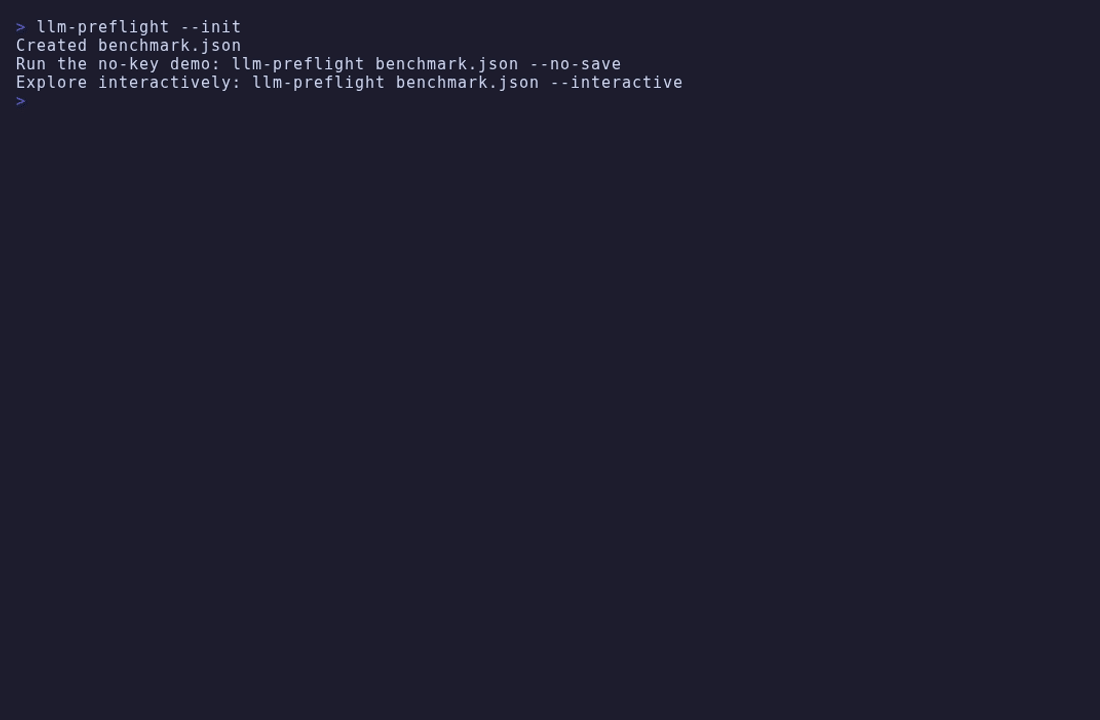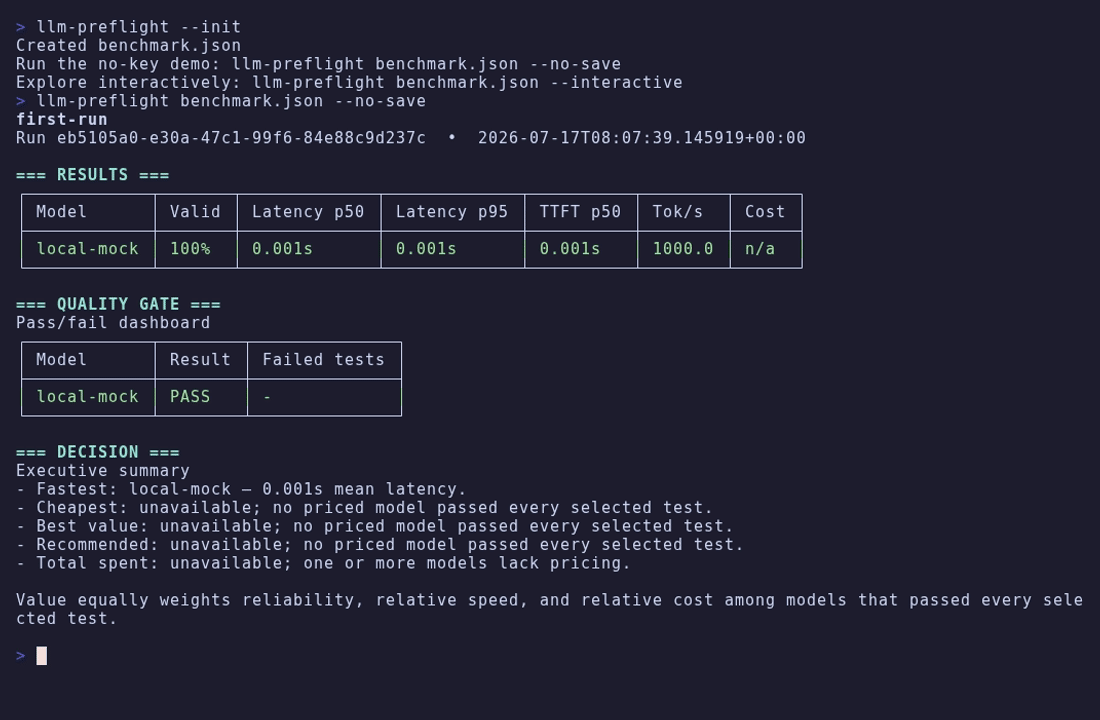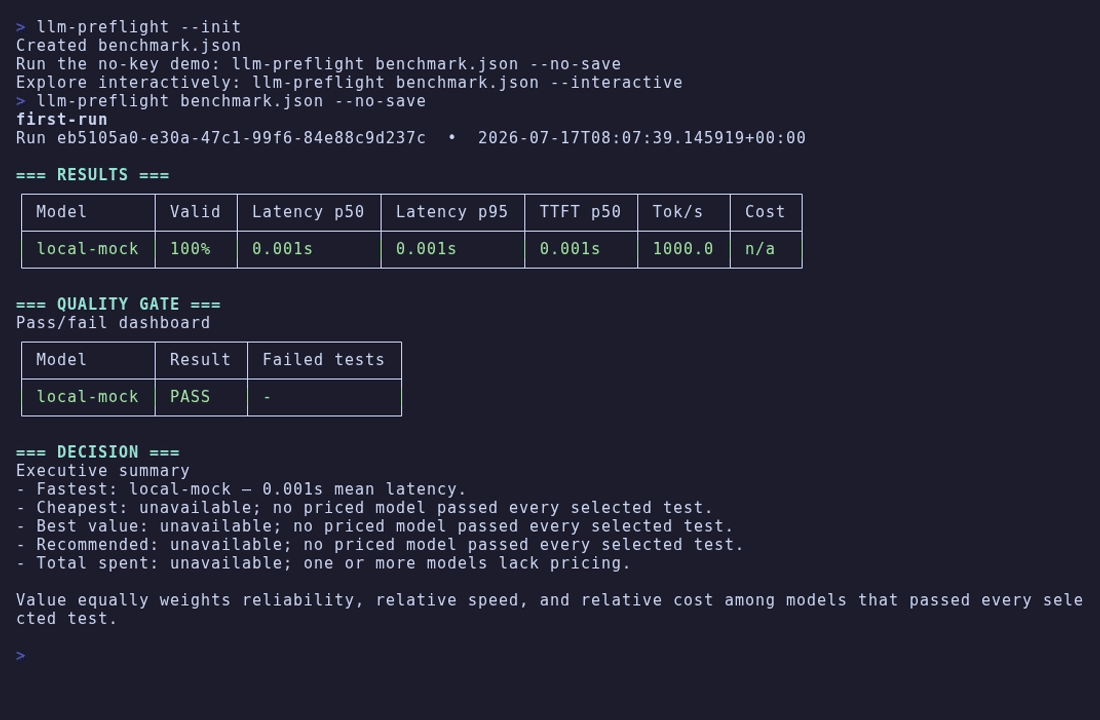
Catch LLM integration regressions before they ship. LLM Preflight is a local contract preflight for model, prompt, structured-output, and provider-call changes. It runs a small cross-provider preflight and compares validated output, response speed, tokens, and estimated cost.
Create and run a deterministic local benchmark—no API key or network request:
python3 -m pip install llm-preflight
llm-preflight init
llm-preflight benchmark.json --no-save
From a source checkout:
python3 -m llm_preflight init
python3 -m llm_preflight benchmark.json --no-save
init never overwrites an existing config. It creates a mock benchmark so
you can see the report and exit behavior before making a paid request.
Its result is intentionally inconclusive (exit code 3): a local mock
validates configuration and output handling, but cannot approve a live model.
llm-preflight-mcp --workspace "$PWD", then use the
MCP server guide
for your client configuration.flowchart LR
A[Integration change] --> B[No-spend validation\ndoctor, pricing, dry run]
B --> C{Human reviews\nevidence and cost bound}
C -->|Explicit approval| D[Bounded paid smoke]
C -->|No approval or missing evidence| E[Inconclusive: fix or stop]
D --> F[Local evidence for\nproduction approval]
LLM Preflight is local evidence, not production approval. It is not a hosted evaluation platform, tracing system, RAG framework, or public leaderboard. Its results apply to your account, network, prompts, and validation rules.
[!WARNING] Live benchmarks make paid API requests. Start with the no-key demo, preview the plan before a live run, and keep limits and repetitions small.
Works as a CLI, GitHub Action, and local MCP server. Every path starts with no-spend validation and planning; a live provider run remains an explicit, bounded human-approved step. See the GitHub Action guide or the MCP server guide.
For earlier releases, see the changelog.
Mission: help engineers catch LLM integration regressions before shipping a change.
Vision: every LLM-related pull request carries reproducible evidence of compatibility, latency, and cost.
Positioning: LLM Preflight is a local CLI and CI tool that checks an application's LLM contract and reports compatibility, latency, and estimated cost before a change ships.
It is built for small engineering teams maintaining AI features. Coding agents can run the same checks, while engineers own the decision. Read the north star and the AI implementation testing guide for the intended workflow and boundaries.
Switch a model or provider. Run the bounded migration check, then add the contract test your feature needs.
Check a prompt, schema, parser, or tool change. Define an explicit
output contract
before the smoke, then run llm-preflight benchmark.json --contract-check
to prove local accepted/rejected fixtures and lint declared tool schemas.
Plan an agent-made change. Run llm-preflight benchmark.json --change-plan
before the ordinary no-spend checks. It identifies static model and contract
signals in local Git changes, but never authorizes a paid run.
Review a newly discovered model. Refresh metadata, then prepare—not run— a bounded candidate plan:
llm-preflight catalog refresh benchmarks/watch.json
llm-preflight catalog prepare benchmarks/watch.json \
  --against benchmarks/approved.json --output benchmarks/candidates.json
llm-preflight benchmarks/candidates.json --migration-check --dry-run
Only explicitly approved, fully evidenced models proceed to paid work; see the model catalogue guide.
Investigate a provider or price change. Run --doctor,
--pricing-check, and a dry-run; report a suspected regression through the
redacted issue forms.
Automate a known contract. Use the no-spend GitHub Action or the
CI guide
with a saved baseline and --ci.
It measures deterministic test validity, end-to-end latency (p50/p95), time to first token, throughput when the stream is incremental and usage is available, token totals, and estimated cost. Result files retain request metadata and per-request observations for reproducibility.
"Deterministic" describes the validator, not the model: every response is checked against explicit structural rules — a regular expression, a JSON shape, an exact routing label — so the same response always produces the same verdict. The tool does not score semantic quality; that is your task-specific evaluation, and it stays out of scope on purpose.
A completed preflight retains per-request observations and a machine-readable decision: contract validity, latency (including TTFT where observable), token usage, estimated cost, pricing evidence, and blocking warnings. The terminal summary is a convenience; automation should consume the saved JSON decision.
That evidence applies to your account, network, prompts, and validator at one time—not a universal model ranking. For a complete interactive example, see interactive runs.
Python 3.10+ is required. There are no third-party runtime dependencies:
pip install llm-preflight installs this package and nothing else, and the
CLI runs on the Python standard library alone. Development tools (pytest,
ruff, mypy) are optional extras that never reach a production install.
cp benchmark.example.json benchmark.json
cp .env.example .env.production
# Edit benchmark.json and add only the provider keys you use.
python3 -m llm_preflight benchmark.json --dry-run
python3 -m llm_preflight benchmark.json
The CLI reads .env.production beside the config without overriding environment
variables already set by your shell. Use --no-env-file or --env-file PATH
when needed. Runs print a terminal report and, unless --no-save is used,
write JSON and Markdown results under results/.
Install the command globally in a virtual environment if preferred:
python3 -m pip install llm-preflight
llm-preflight --init
Run --doctor and --dry-run before the final command. They make no generation
requests; the final command is the paid work.
This is the core workflow. Put your approved model and candidate model in one config, then run the small response-and-contract preflight:
llm-preflight benchmark.json --migration-check --dry-run
llm-preflight benchmark.json --migration-check
It sends three short representative cases to each selected model, once each. It answers: did the API work, did each response meet the basic contract, and how quickly did the provider start and finish responding? It is a cheap compatibility check, not a statistical performance conclusion.
When that passes, run the task-specific checks that match your application—for
example exact-routing-check or structured-output-check—before approving a
switch.
Use custom contract tests to express the outputs your
own feature must preserve.
Give an agent the same evidence you would use yourself: a reviewed config, an explicit output contract, and a dry run before paid work. Start with the recommended five-check suite:
# No generation request: inspect credentials, model selection, and paid-work plan.
llm-preflight benchmark.json --doctor --json
llm-preflight benchmark.json --tests agent-smoke --smoke --dry-run --json

# Paid run, only after reviewing the plan.
llm-preflight benchmark.json --tests agent-smoke --smoke --json --no-save
An agent should not infer model IDs, weaken a validator to turn a failure into a pass, or approve a model without an explicit instruction. The compact LLM and coding-agent guide covers commands, result JSON, exit codes, and automation guardrails. The AI implementation testing guide shows how to make this validation an agent's default testing step.
Use the local stdio MCP server when an agent needs the preflight evidence without shell parsing or arbitrary command execution:
{
  "mcpServers": {
    "llm-preflight": {
      "command": "llm-preflight-mcp",
      "args": ["--workspace", "/absolute/path/to/repository"]
    }
  }
}
It exposes only four tools: validate a config, prepare a dry-run plan, run an explicitly confirmed preflight, and compare saved baselines. The first, second, and fourth tools never contact providers or load credentials. A live run still needs an explicit paid-run confirmation. See the MCP server guide for tool semantics, workspace boundaries, and the safe agent workflow.
# Inspect configuration, credentials, and model selection without generation.
# --doctor provides pricing advisory; use --pricing-check as the fail-closed coverage gate.
llm-preflight benchmark.json --doctor
llm-preflight benchmark.json --pricing-check
llm-preflight benchmark.json --dry-run

# Run a reduced live benchmark.
llm-preflight benchmark.json --smoke

# Run a single ad hoc prompt.
llm-preflight --quick "Return only valid JSON with a status field." \
  --models openai:gpt-5.4-mini
For advanced discovery, interactive runs, CI, baselines, replay, and stop modes, see workflows. For models, environment files, custom prompts, and provider-specific options, see configuration.
The CLI distinguishes API FAIL (transport, credentials, provider, or request
failure) from API OK / TEST FAIL (a response that fails your validator).
Recommendations only consider models that pass every selected test.
Several good tools live near this space. Use them when their job is your job:
llm (Simon Willison) — a general multi-provider CLI for running
prompts, not a comparison harness.LLM Preflight does one narrower job: the local go/no-go check in the moment before an LLM integration change. Your prompt, candidate models, structural validation, latency, and cost — one command, one report, no hosted service, no telemetry, and no vendor between you and the verdict.
Start at the documentation homepage, then choose the path that matches your work:
Contributions are welcome; see CONTRIBUTING.md. Released under the MIT License.
FAQs
Local, cross-provider preflight checks for LLM integration changes
The pypi package llm-preflight receives a total of 478 weekly downloads. As such, llm-preflight popularity was classified as not popular.
We found that llm-preflight demonstrated a healthy version release cadence and project activity because the last version was released less than a year ago. It has 1 open source maintainer collaborating on the project.
Security News
It has been one year since Shai-Hulud made its first appearance on npm.

Research
/Security News
Operators behind PolinRider used a compromised GitHub account to plant malware in four development versions of a Packagist package with 700,000+ downloads.

Security News
GitHub Actions now supports cache-mode, a least-privilege control on the Actions cache aimed at the cache poisoning technique behind recent compromises.